
⚠️ Researchers are opening the black box of AI understanding
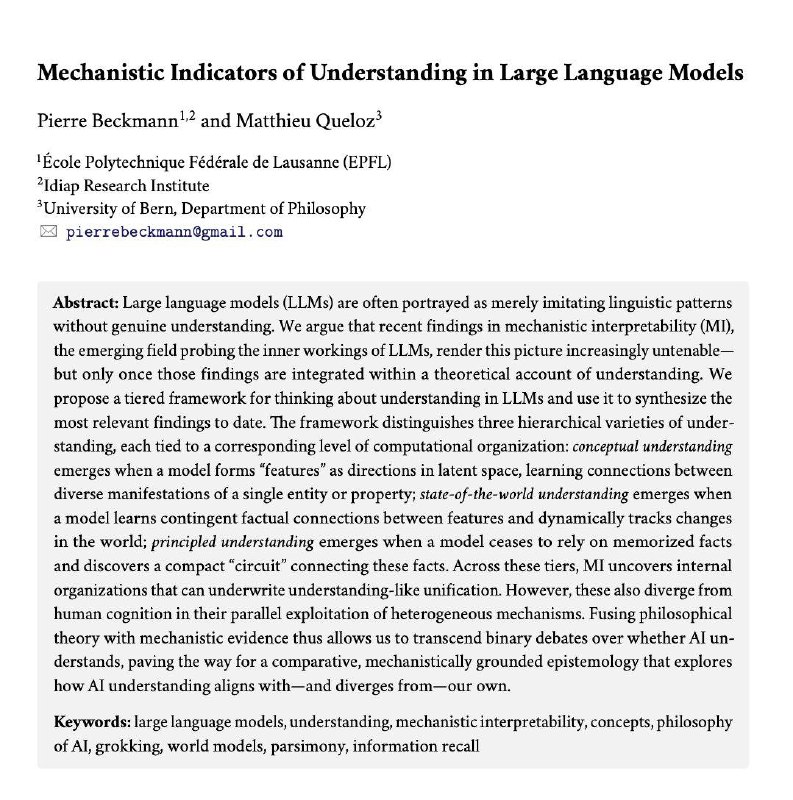
Mechanistic interpretability is giving researchers a closer look at what happens inside large language models and how they develop internal representations that go beyond simple word associations.
Studies have found that models can develop internal features representing concepts, track relationships between facts, and sometimes discover general rules that let them solve problems they haven’t seen before.
One intriguing phenomenon is called “grokking”: during training, a model can suddenly shift from memorizing examples to generalizing from underlying patterns. In some experiments, performance on new problems improves dramatically even after a long period of apparent failure.
This suggests that neural networks can discover compact rules from data without anyone explicitly programming those rules into them.
These findings don’t prove that AI understands reality the same way humans do, or that models simply erase memorized facts and replace them with a complete world model.
Source.
@aipost 🏴
Post #8462
797
- 🤡 4
- 😡 4
- 😐 1
- 👀 1