TGViewer
Channel Public Channel
Kube Architect

Kube Architect

@kubearchitect

News and links on architecting and developing apps on Kubernetes curated by the @Learnk8s team
Subscribers
8.96K
Photos
1.9K
Videos
453
Links
4K

Showing posts older than #4022 · Back to latest

Older Posts 20 shown
Post #4021 419

Forwarded from KubeFM

A pizza order became a 15-container, 200-trace system.

In Kube Signals episode two, Brian Teller and Mauricio (Salaboy) Salatino examine observability, state management, governance, and trust for non-deterministic agents.

They discuss:

- Why multi-agent runtimes can recreate monolith scaling
- How OpenTelemetry exposes prompts, completions, and decisions
- Why execution history turns agent trust into measurable evidence

Watch: https://ku.bz/TlVjXdnb6

Kubernetes moves too fast to track everything. Learn Kubernetes Weekly filters out the noise to deliver one curated email with useful articles, tutorials, tools, jobs, events, and CFPs. Subscribe to Learn Kubernetes Weekly.
Post #4020 507
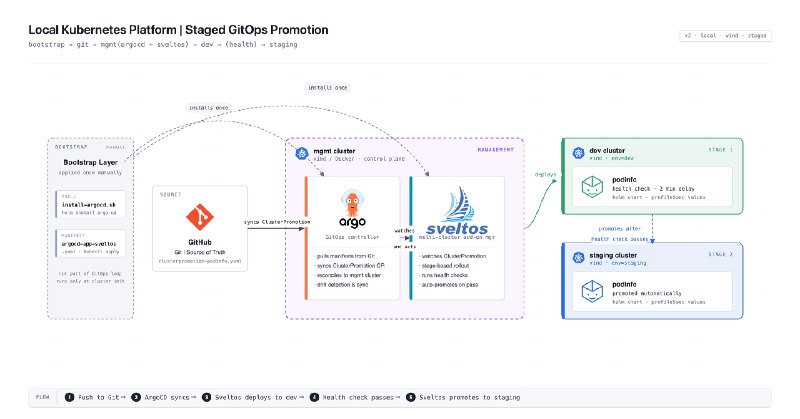
This article shows how Sveltos ClusterPromotion promotes a config from dev to staging to production only when health checks pass, and why letting Argo CD and Sveltos manage each other deleted Argo CD.

More: https://ku.bz/sJZhQf25J
  • 🔥 1
  • 😁 1
Post #4019 459

Forwarded from LearnKube news

kubectl tree is a kubectl plugin that follows ownerReferences and prints the whole object tree under a Deployment or custom resource, so you can see what created what.

More: https://ku.bz/D2qCz0wDD
Post #4018 582
This article lays out a production EKS setup where Karpenter keeps a cheap On-Demand baseline and absorbs traffic spikes with Spot nodes that drain safely when AWS reclaims them.

More: https://ku.bz/f-CnXzXxb
Post #4017 516

Forwarded from KubeFM

Molly Sheets, Director of Engineering, Kubernetes at Zynga, addresses the common fears and misconceptions that prevent platform teams from adopting multi-tenant Kubernetes environments. She challenges the perfectionist mindset that often paralyzes teams and provides practical guidance for moving forward with shared infrastructure.

Molly emphasizes prioritizing business needs over architectural purity, arguing that teams often get stuck pursuing the "perfect pristine architecture" instead of focusing on what actually serves their organization. She directly addresses the fear that shared environments will compromise service quality, particularly around security and account isolation concerns.

Watch the full episode: https://ku.bz/Rmpl8948_
Post #4016 627
This case study shows how a student team built a multi-tenant PostgreSQL DBaaS on Kubernetes with Patroni for failover and PgBouncer for pooling, and what they had to redo.

More: https://ku.bz/_FZ-k558p
Post #4015 659
This article describes Silex, a homemade Kubernetes ingress controller with a Go control plane and a Rust data plane, and benchmarks it against the Nginx ingress controller.

More: https://ku.bz/zTSm2MLtf
Post #4014 743
This tutorial shows how to link three GKE clusters with Linkerd multicluster, mixing federation and mirroring so a service keeps answering even when a whole cluster disappears.

More: https://ku.bz/RMhY6y-2_
Post #4013 662

Forwarded from KubeFM

Brian Donelan, VP Cloud Platform Engineering @ JPMorganChase, breaks down the key differences between KEDA (Kubernetes Event-Driven Autoscaler) and traditional Kubernetes autoscaling mechanisms. He explains how KEDA fundamentally changes the scaling paradigm from resource-based metrics to event-driven triggers, enabling more responsive and cost-effective scaling strategies.

The explanation provides practical context for when KEDA excels: batch processing jobs, event-driven microservices, development environments, and serverless-style workloads on Kubernetes.

Watch the full episode: https://ku.bz/sFd8TL1cS
  • 👍 1
Post #4012 520
This case study shows how a team turned an old chat export into a searchable archive with OpenSearch, a Spring Boot app and a Kubernetes deployment behind HTTPS.

More: https://ku.bz/Y2c8-D7Z3
  • ❤ 1
Post #4011 684
This case study shows how Inditex reclaims idle node capacity with an open-source overcommit operator that rewrites pod requests through a mutating webhook, based on priority class.

More: https://ku.bz/XV3rLBhJr
Post #4010 536

Forwarded from LearnKube news

This case study walks through a production debugging session where orphaned Kubernetes pods kept blocking new deployments due to a race condition between the job controller, garbage collector, and an undocumented default propagation policy behavior.

More: https://ku.bz/NmswYT7Zd
Post #4009 567
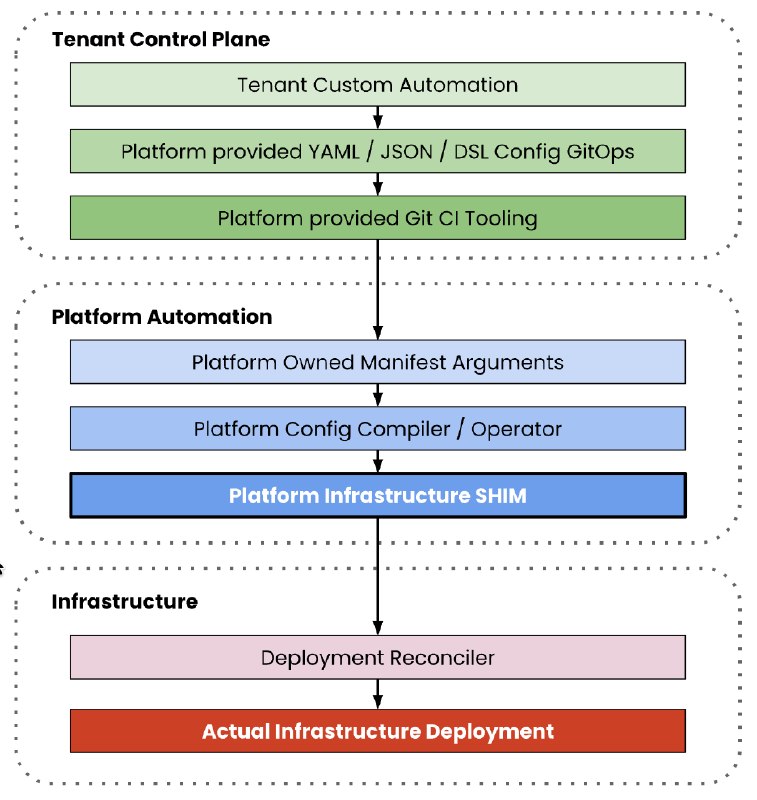
This case study shows how to use Source Hydrated Infrastructure Models (SHIM), a GitOps pattern that commits fully rendered infrastructure manifests to Git for explicit auditing and reconciliation.

More: https://ku.bz/LGRcYxQGy
Post #4008 504

Forwarded from KubeFM

Oleksii Kolodiazhnyi, Senior Architect @ Mirantis, explains the fundamental reasoning behind using graphs and visual diagrams for Kubernetes workload assessment.

Oleksii emphasizes that graphs serve two critical purposes: they provide an intuitive way to represent system architecture, and they dramatically improve information consumption speed compared to text-based descriptions.

Watch the full episode: https://ku.bz/zDThxGQsP
Post #4007 424

Forwarded from LearnKube news

200 issues. More than 77,000 Kubernetes engineers. Thank you to all of you reading it 🎉

In Learn Kubernetes Weekly 200:

🤖 Benchmarking LLM Inference with Production Agent Traces
🔌 Two New Headlamp Plugins
🌐 Migrating from ingress-NGINX to Envoy Gateway
🐘 Building High-Availability PostgreSQL on Kubernetes

Read it: https://kube.today/issues/200
Post #4006 525
This article shows how CloudNativePG replaces Patroni, HAProxy and barman with four Kubernetes resources that handle failover, backups and connection pooling for PostgreSQL.

More: https://ku.bz/xbcrK9px3
Post #4005 589

Forwarded from KubeFM

Andrew Jeffree, Staff Cloud Infrastructure Engineer at SafetyCulture, explains the strategic thinking behind migrating from a Helm-based deployment system to GitOps with ArgoCD.

Andrew details the core problems they aimed to solve: eliminating places where configurations could drift, reducing the need to add pipeline steps as they scaled to more Kubernetes clusters, and addressing developer confusion where green pipelines only meant validation passed, not that changes were actually deployed.

Watch the full episode: https://ku.bz/Xvyp1_Qcv
Post #4004 455

Forwarded from KubeFM

Kubernetes is ready for databases. Most teams are not.

In KubeSelect episode two, Salman Iqbal and Bart Farrell test this claim with Kat Cosgrove of VillageSQL.

Kat covers:

- Modern Kubernetes storage
- Operators and database expertise
- Team readiness
- Managed database tradeoffs

Kat's verdict: this is now a people problem.

Watch the episode: https://ku.bz/7yDWlP8T5

Kubernetes moves too fast to track everything. Learn Kubernetes Weekly filters out the noise to deliver one curated email with useful articles, tutorials, tools, jobs, events, and CFPs. Subscribe to Learn Kubernetes Weekly.
Post #4003 532
This case study shows how a team migrated their Spring Boot microservices from Azure App Service to AKS, resulting in a 25% reduction in their infrastructure bill.

More: https://ku.bz/9kf3cH2K4
Post #4002 639
This case study tells how a team deleted their EKS cluster and moved to three plain servers with Kamal, dropping the bill from $1,200 to $180 a month and deploying in about half a minute.

More: https://ku.bz/fJCq-Ynbr
  • 😁 5
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →