TGViewer
Channel Public Channel
Kube Architect

Kube Architect

@kubearchitect

News and links on architecting and developing apps on Kubernetes curated by the @Learnk8s team
Subscribers
8.96K
Photos
1.9K
Videos
453
Links
4K

Showing posts older than #4002 · Back to latest

Older Posts 20 shown
Post #4001 637
This article explains how Kubernetes 1.36 moves scheduling toward whole workloads with the new PodGroup API, so AI and batch jobs get all their pods placed together instead of one by one.

More: https://ku.bz/w1nVq3D0l
Post #4000 707

Forwarded from Kube Events

We have 25 free tickets for Civo Navigate London 2026!

Explore cloud, AI and data sovereignty with 800+ tech leaders and builders.

📆 September 22, 2026
📍 Convene, 155 Bishopsgate, London

Get in touch at hello@kube.events to get yours.
https://www.civo.com/navigate/london/2026
  • ❤ 2
Post #3999 754
This tutorial builds a local multi-cluster lab with vind, then uses Sveltos and Argo CD to deploy to every cluster that carries the right label.

More: https://ku.bz/bQmmMLsMk
  • 👍 2
Post #3998 751
k8s-overcommit Operator is a Kubernetes operator that trims pod CPU and memory requests based on per-workload overcommit classes, so you can pack more onto a cluster without touching the limits.

More: https://ku.bz/s3P-hs52K
Post #3997 806
This case study walks through moving from ingress-NGINX to Envoy Gateway, including the mistakes made on the way, like nginx annotations that do not map one-to-one onto Gateway API policies.

More: https://ku.bz/mG7jhf-Q7
Post #3996 721

Forwarded from LearnKube news

Kubernetes production readiness checklist is a free, open checklist for taking applications to production on Kubernetes, covering app design, manifests, security, scaling and going live.

More: https://ku.bz/9zSG4sjDP
Post #3995 693
KubeElasti scales idle Kubernetes services down to zero and wakes them on the first request, holding that traffic in a proxy queue so nothing is lost while the pods start.

More: https://ku.bz/zbxX-YGrw
Post #3994 637

Forwarded from KubeFM

Multi-cluster Kubernetes usually breaks down in operations, not in the diagram.

Shani Adadi Kazaz says maintenance, tool sprawl, and small per-team configuration changes are what turn shared templates into inconsistent environments.

The big lesson is that scale amplifies operational drift unless teams standardize early.


Watch the full interview: https://ku.bz/kThBjp3Lj
Post #3993 518
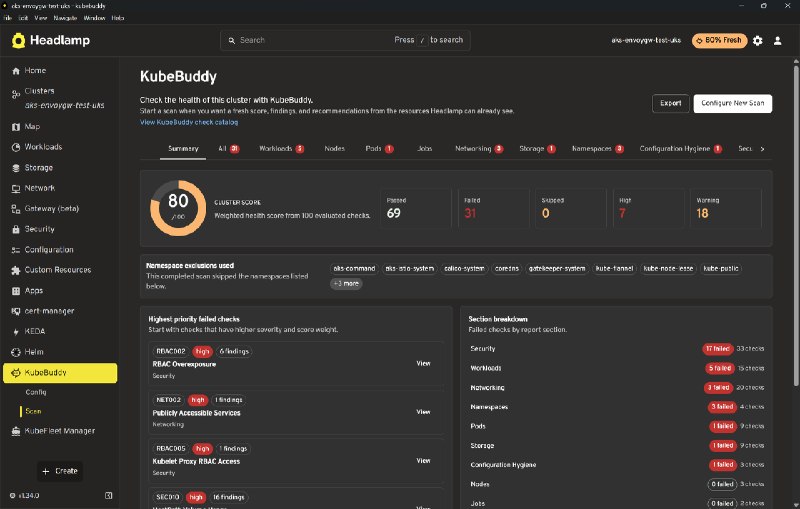
This article introduces two new Headlamp plugins: KubeBuddy for browser-side Kubernetes cluster auditing and Headlamp Theme Builder for creating custom dashboard themes.

More: https://ku.bz/tK4YdwtgW
  • 👍 1
Post #3992 513
Polykube is a GitOps-native operator that runs the same workloads across clusters and clouds, with no central control plane and Cilium ClusterMesh carrying cross-cluster traffic.

More: https://ku.bz/0WrtnwJND
Post #3991 562

Forwarded from KubeFM

Thibault Jamet, DevOps and Technical Product Owner @ Adevinta, breaks down the three core components of Vertical Pod Autoscaler and explains how they work together to automatically manage container resources.

He walks through the recommender that analyzes CPU and memory usage over time, the updater that evicts pods when they don't match recommendations, and the mutating webhook that modifies pod definitions in-flight while leaving the original deployment unchanged.

Watch the full episode: https://ku.bz/rf1pbWXdN
  • ❤ 1
Post #3990 459

Forwarded from LearnKube news

This week on Learn Kubernetes Weekly 199:

🔥 How Netflix Simplified Batch Compute with Kueue
💡 Server-side Apply: What Happens When You Run kubectl apply
🌐 Kubernetes Is Migrating from SPDY to WebSockets
🔁 How I Learned to Stop Worrying and Love the Reconciliation Loop
🔒 Securing CI/CD for an Open Source Project: Lessons from Cilium

Read it now: https://kube.today/issues/199

⭐️ This newsletter is brought to you by LearnKube — master Kubernetes with hands-on training designed for engineers who want to learn the smart way https://ku.bz/hypSbyc-V
Post #3989 773
This article explains what really happens when you run kubectl apply, and how server-side apply moves field ownership into the API server so Helm, Argo CD and HPAs hit conflicts.

More: https://ku.bz/KZ_RzWBV5
Post #3988 683
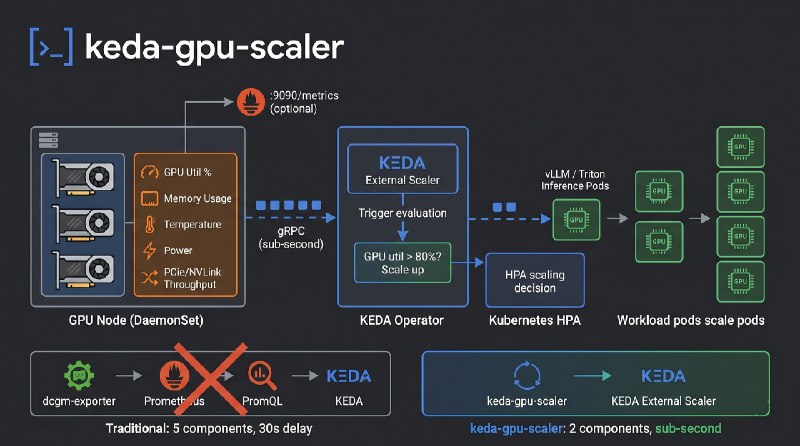
keda-gpu-scaler is a KEDA external scaler that reads GPU metrics from NVML on each node, so vLLM and Triton deployments scale on real GPU load instead of CPU, including scale to zero.

More: https://ku.bz/KB6slMgk4
Post #3987 600

Forwarded from KubeFM

GKE Autopilot does not just manage the cluster for you. It also shapes the cost model.

Reid Vandewiele explains why Autopilot’s guaranteed QoS approach makes Kubernetes optimization harder by removing a lot of the over-provisioning room that teams usually rely on to control spend.


Watch the full interview: https://ku.bz/9RmbpWGng
Post #3986 537

Forwarded from KubeFM

Kube Select is here. It tests one claim: more telemetry does not yield better decisions.

Henrik Rexed of Dynatrace joins hosts Salman Iqbal and Bart Farrell to test it.

You will learn:

- how service ownership gives telemetry incident context
- why proxy metrics can produce extreme data volume
- how AI agents run queries before human review

Watch: https://ku.bz/848pmBN5_

🌟 Kubernetes moves too fast to track everything. Learn Kubernetes Weekly filters out the noise to deliver one curated email with useful articles, tutorials, tools, jobs, events, and CFPs. Subscribe to Learn Kubernetes Weekly.
Post #3985 536
This guide shows you how to architect a multi-cluster Kubernetes environment using Rancher for governance, vCluster for cost-efficient isolation, and Kargo for automated GitOps promotion pipelines.

More: https://ku.bz/_BFwl6fKW
Post #3984 580
Valkey Operator is a Kubernetes operator that automates deployment and lifecycle management of Valkey clusters and instances with features like automated installation and configuration management.

More: https://ku.bz/QH0z4Sg5l
Post #3983 612

Forwarded from LearnKube news

Running Java on Kubernetes? CPU and memory limits affect much more than scheduling.

A 4 GiB heap requires a container larger than 4 GiB. Fractional CPU limits can also change the processor count that HotSpot sees.

In our new article, you will learn:

- Why JVM heap size and container memory are different boundaries
- How CPU limits affect garbage collection, worker pools, and application performance
- Which JVM and container metrics to collect when validating resource settings under load

The article also includes practical experiments and an interactive configuration calculator.

Read: https://learnkube.com/java-jvm-kubernetes-requests-limits

Author: Gulcan!
Post #3982 712
This article explains how to deploy agentic AI on Kubernetes using a four-layer architectural stack.

It details model inference, fine-tuning, and agent orchestration using tools like KAITO, Ray, and MCP.

More: https://ku.bz/Gw2X5272D
  • 👍 1
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →