TGViewer
Channel Public Channel
Data science/ML/AI

Data science/ML/AI

@datascience_bds

Data science and machine learning hub

Python, SQL, stats, ML, deep learning, projects, PDFs, roadmaps and AI resources.

For beginners, data scientists and ML engineers
πŸ‘‰ https://rebrand.ly/bigdatachannels

DMCA: @disclosure_bds
Contact: @mldatascientist
Subscribers
14K
Photos
608
Videos
7
Links
341

Showing posts older than #1330 Β· Back to latest

Older Posts 20 shown
Post #1329 1.23K
🧩 Why One-Hot Encoding Exists

Machine learning models don't understand words.
They understand numbers.

So how do you feed a value like:
Color = Red


You can't simply write:
Red = 1
Blue = 2
Green = 3


The model might think Green > Blue > Red, even though colors have no natural order.

Instead, we create separate columns:
Red    1 0 0
Blue 0 1 0
Green 0 0 1

This is called One-Hot Encoding. It represents categories without introducing fake relationships.
  • ❀ 8
Post #1328 1.22K
🚨 UC Berkeley just open-sourced FreeToken.

It claims 2–4Γ— faster local LLM inference than Ollama, and the wild part is the models it can run:
β€’ Qwen3.6-35B on 8GB VRAM β†’ 39.3 tok/s
β€’ DeepSeek-V4-Flash 284B on 32GB VRAM β†’ 22 tok/s
β€’ GLM-5.2 753B on 96GB VRAM β†’ 14.9 tok/s

How? These are Mixture-of-Experts models. A 35B model doesn't actually use all 35B parameters for every token.

FreeToken keeps the experts in system RAM and intelligently decides whether a missing expert should be sent to the GPU or computed on the CPU.

The good part is the best strategy depends on your exact machine. A 5090 desktop and an 8GB laptop may want completely opposite approaches.

It also checkpoints agent context, so coding agents don't repeatedly prefill thousands of unchanged tokens.

Open weights don't mean much if nobody can afford the hardware to run them. FreeToken is attacking that gap.

πŸ“„ Paper: https://arxiv.org/pdf/2608.16157
πŸ’» Repo: https://github.com/FlashML-org/FreeToken
  • ❀ 3
  • πŸ”₯ 3
Post #1326 1.12K

Forwarded from Programming Quiz Channel

Topic: SQL

πŸ” Quick look before the question:

SELECT e.name, e.salary
FROM employees e
WHERE e.salary > (
SELECT AVG(salary)
FROM employees
WHERE department = e.department
);
Post #1325 1.28K
🐼 One Pandas Function That Can Save You From Ugly if/else

Suppose you want to classify customers:
spending >= 1000 β†’ VIP
spending >= 500 β†’ Regular
otherwise β†’ Low


You could write a complicated function.
Or:
import numpy as np

df["segment"] = np.select(
[
df["spending"] >= 1000,
df["spending"] >= 500
],
[
"VIP",
"Regular"
],
default="Low"
)

Now the rules are visible directly in the code.

This becomes especially useful when you have several conditions.
  • ❀ 5
Post #1323 1.23K
πŸ“š 12 Free Statistics Resources Worth Bookmarking

If your statistics foundation is weak, you'll spend more time memorizing algorithms than understanding them.
Here are 12 resources that are genuinely worth your time.

1. Penn State STAT Online
Complete university-level statistics courses available for free.

2. Seeing Theory
Interactive visualizations that make probability and statistics much easier to grasp.

3. OpenIntro Statistics
A free, beginner-friendly statistics textbook with exercises.

4. Introduction to Statistical Learning (ISLR)
One of the best books for learning statistical learning with practical R and Python examples.

5. Khan Academy Statistics & Probability
Excellent if you're starting from scratch.

6. StatQuest
Probably the clearest explanations of statistics and machine learning on YouTube.

7. Stanford Online (Statistics Courses)
Free lectures covering probability and statistical thinking.

8. Harvard CS109 Data Science
Statistics taught through real-world data analysis.

9. ProbabilityCourse.com
One of the best free references for probability concepts.

10. Statistics by Jim
Straightforward articles explaining common statistical concepts.

11. NIST e-Handbook of Statistical Methods
A comprehensive reference used by engineers, researchers, and analysts.

12. Cross Validated (Stack Exchange)
When you're stuck on a statistics question, chances are it's already been answered here.

⭐️ Bookmark this.

@datascience_bds
  • πŸ”₯ 5
Post #1322 1.14K
RAG vs. Graph RAG vs. Agentic RAG

Standard RAG embeds documents into vectors and retrieves similar chunks.
Effective for direct factual lookups, but fails when queries require connecting facts across multiple documents, as similarity search misses relationships between chunks.

Graph RAG adds a knowledge graph layer. An LLM extracts entities and relationships during indexing; retrieval traverses these connections rather than relying solely on embedding similarity. This enables multi-hop queries.

Example: Vector search retrieves "checkout service uses payments API" and "cluster-3 maintenance Friday" but misses "payments API runs on cluster-3" because the middle fact lacks query keywords. Graph traversal connects these entities, finding the full path in one query.

Agentic RAG uses an LLM agent to dynamically decide which tools to invoke, which sources to query, and in what order, rather than using a fixed pipeline.
  • ❀ 4
  • πŸ‘ 1
Post #1321 1.15K

Forwarded from AI Revolution

The #1 problem with local AI seems to be solved now.

There’s a free tool called canIrun.ai that checks your hardware and tells you which models will actually run well before you download anything.

So instead of guessing and hitting out-of-memory errors…it grades every model against your machine.

What it does (right in your browser, no install):
β†’ detects your setup (RAM / CPU / GPU / VRAM)
β†’ scores each model for fit, speed, and context length
β†’ grades every quantization level (Q4_K_M, Q6_K, Q8_0, etc.)
β†’ labels what runs great vs okay vs too heavy

It covers most of the open-weight stack, Llama, Qwen, Gemma, Mistral, DeepSeek, Phi and more, pulling requirements from llama.cpp, Ollama, and LM Studio.

And it’s fully opensource.
  • ❀ 6
Post #1320 1.17K
Normal Distribution vs t-Distribution
  • ❀ 6
  • πŸ”₯ 2
Post #1319 1.26K
πŸ“ˆ Mean vs Median

Suppose these are five salaries:
$35k, $38k, $42k, $44k, $2.5M

Mean (average): $531,800
Median (middle value): $42,000

The average suggests everyone is wealthy.
The median tells a completely different story.

πŸ‘‰ Whenever your data contains extreme values (called outliers), the median often represents the data much better than the mean.

That's why you'll often see median house prices and median income reported in the news.
  • ❀ 6
Post #1318 1.34K
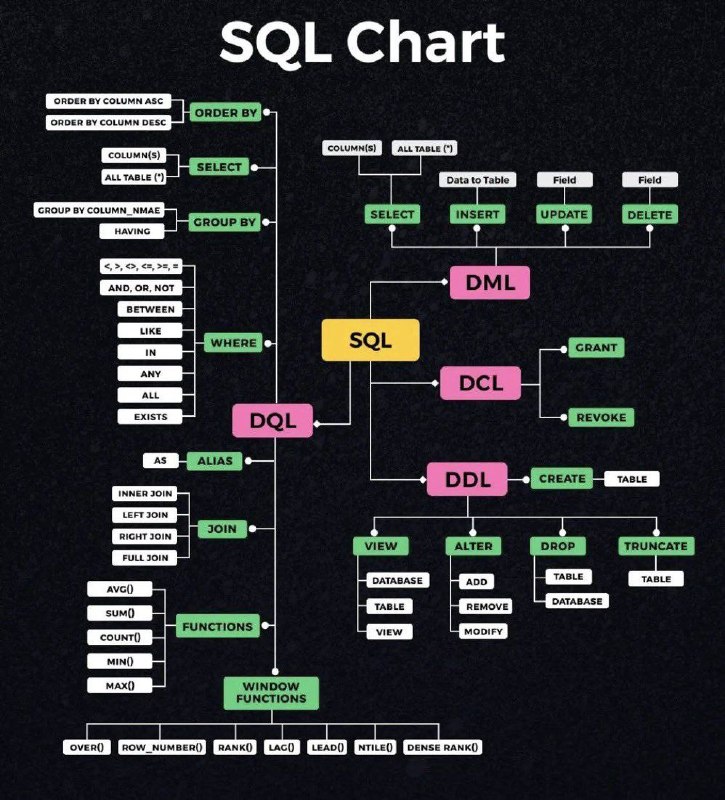
SQL CHART
  • ❀ 6
  • πŸ”₯ 2
Post #1317 1.45K
πŸ“‰ Why We Split Data

If you train and evaluate a model using the exact same dataset, you're only testing how well it remembers.

That's why datasets are usually split into:
πŸ‘‰ Training set β†’ The model learns from this.
πŸ‘‰ Validation set β†’ Used to tune model settings.
πŸ‘‰ Test set β†’ Used only once at the end to measure real performance.

Think of it like studying for an exam.
Reading the textbook is training. Practice questions are validation. The final exam is the test set.
  • ❀ 5
  • πŸ”₯ 3
Post #1316 1.23K
🐼 Pandas: The Dangerous Difference Between loc and iloc

Both select data. That's why beginners mix them up.

The simplest way to remember is:
loc β†’ labels
iloc β†’ positions

df.loc[5]

means:
Give me the row whose label is 5.


On the other hand:
df.iloc[5]

means:
Give me the 6th row.


Those are not necessarily the same row. Especially after filtering.
If your DataFrame index looks like:
0
1
4
7
9

then:
df.iloc[2]

returns the row at position 2. That's index label 4.

This tiny distinction causes a surprising number of bugs.
  • ❀ 6
Post #1315 1.28K
πŸ“Š 10 Websites Every Data Scientist Should Bookmark
Whether you're learning data science or building production models, they'll save you a lot of time.

Google Dataset Search
Find millions of public datasets from universities, governments, and research organizations.

Our World in Data
High quality datasets with well-researched visualizations on health, climate, economics, energy, education, and more.

UCI Machine Learning Repository
One of the most widely used collections of datasets for machine learning practice and research.

Papers with Code
Research papers linked with official implementations, datasets, and benchmark leaderboards.

OpenML
A platform for sharing datasets, experiments, and reproducible machine learning workflows.

Data.gov
Over 300,000 public datasets published by the U.S. government.

Awesome Public Datasets
A massive GitHub repository of datasets organized by category.

Google Colab
Run Python notebooks in the cloud with free GPU access for many workloads.

Hugging Face Datasets
Thousands of ready-to-use datasets for NLP, computer vision, audio, and more.

Kaggle Datasets
Millions of datasets shared by the data science community.

⭐️ Save this post. You'll probably use these throughout your data science journey.
  • ❀ 7
Post #1314 1.12K
12 AI Frameworks Every AI Engineer Should Know
  • ❀ 8
Post #1313 1.14K

Forwarded from Free Programming Books

πŸ“˜ R for Data Science

✍️ Authors: Garrett Grolemund, Hadley Wickham

πŸ”— Read Online

#Datascience #R
────────────────────
πŸ‘‰ @free_programming_books_bds πŸ‘ˆ
  • ❀ 5
Post #1312 1.13K
βœ… SQL Essentials for Data Science πŸ—„

πŸ‘‰ SQL remains an absolute must-have skill for anyone working in Data Science or Analytics.

Virtually every organization manages its core information inside databases, and SQL is the key to extracting, transforming, and analyzing that data.

πŸ”Ή 1. What is SQL?

SQL = Structured Query Language

πŸ‘‰ Used to:

βœ”οΈ Query data
βœ”οΈ Filter records
βœ”οΈ Perform calculations
βœ”οΈ Uncover business insights

πŸ”₯ 2. Popular Database Engines

βœ”οΈ PostgreSQL
βœ”οΈ MySQL
βœ”οΈ Snowflake
βœ”οΈ Google BigQuery

πŸ”Ή 3. Basic SQL Query


βœ… The SELECT Clause

Used to fetch records from a table.

SELECT * FROM customers;

πŸ‘‰ * retrieves every single column.

πŸ”Ή 4. Fetch Specific Columns

SELECT full_name, total_spent FROM customers;

πŸ”Ή 5. WHERE Clause

Used to apply filters to your data.

SELECT * FROM customers WHERE age >= 25;

πŸ”Ή 6. ORDER BY

Sort your results.

SELECT * FROM customers ORDER BY total_spent DESC;

βœ”οΈ ASC β†’ Ascending (Lowest to Highest)
βœ”οΈ DESC β†’ Descending (Highest to Lowest)

πŸ”Ή 7. Aggregate Functions

Used for summary statistics.

Function: COUNT()
Purpose: Counts the number of rows

Function: SUM()
Purpose: Adds values together

Function: AVG()
Purpose: Finds the mean value

Function: MAX()
Purpose: Finds the highest value

Function: MIN()
Purpose: Finds the lowest value

βœ… Example

SELECT AVG(total_spent) FROM customers;

πŸ”Ή 8. GROUP BY

Used to categorize data into buckets.

SELECT country, SUM(total_spent) FROM customers GROUP BY country;

πŸ”Ή 9. Why SQL is Critical?

βœ”οΈ #1 requested technical skill in job descriptions
βœ”οΈ Used daily by analysts, data engineers, & data scientists
βœ”οΈ Scales seamlessly with massive enterprise datasets
  • πŸ”₯ 7
Post #1311 1.16K
❌ Cross Entropy Isn't Measuring Accuracy

Here's something that surprises a lot of people. These two predictions are both correct.

Prediction A
Cat: 51%
Dog: 49%

Prediction B
Cat: 99.9%
Dog: 0.1%

Accuracy treats them exactly the same. Cross Entropy doesn't. It rewards confidence only when the model is correct.

If the true class is "Cat":
Prediction A gets a relatively high loss. Prediction B gets a very small loss.

Now flip the prediction.
Cat: 0.1%
Dog: 99.9%

The loss explodes. That's because Cross Entropy isn't asking:
Did you get it right?

It's asking:
How confident were you in the correct answer?

That's why neural networks optimize Cross Entropy instead of accuracy.
Accuracy is too coarse to guide learning.
  • ❀ 4
  • πŸ‘ 3
Post #1310 1.28K
ML Engineer vs AI Engineer
  • ❀ 7
Post #1309 1.57K
πŸ“If Your Model Suddenly Gets Worse, Check These First

Before retraining everything, inspect:

β€’ Data drift
β€’ Missing values
β€’ Feature distribution changes
β€’ New categories
β€’ Pipeline failures
β€’ Label quality

Production issues are often data problems, not algorithm problems.
  • ❀ 2
  • πŸ‘ 2
Older posts β†’
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook β†’Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 β†’