TGViewer
Channel Public Channel
Data science/ML/AI

Data science/ML/AI

@datascience_bds

Data science and machine learning hub

Python, SQL, stats, ML, deep learning, projects, PDFs, roadmaps and AI resources.

For beginners, data scientists and ML engineers
👉 https://rebrand.ly/bigdatachannels

DMCA: @disclosure_bds
Contact: @mldatascientist
Subscribers
14K
Photos
608
Videos
7
Links
341

Showing posts older than #1309 · Back to latest

Older Posts 19 shown
Post #1308 1.59K
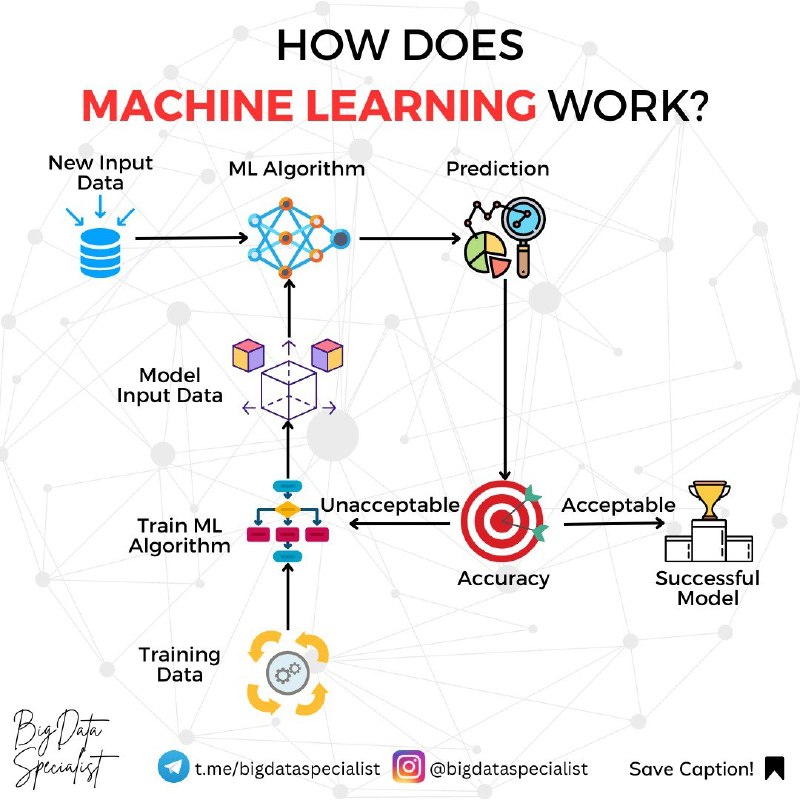
How Does Machine Learning Work?
  • ❤ 4
  • 👍 4
Post #1307 1.58K
15 GitHub Repositories For Machine Learning Engineers
  • ❤ 10
Post #1306 1.53K
List of AI Project Ideas 👨🏻‍💻🤖 -

Beginner Projects

🔹 Sentiment Analyzer
🔹 Image Classifier
🔹 Spam Detection System
🔹 Face Detection
🔹 Chatbot (Rule-based)
🔹 Movie Recommendation System
🔹 Handwritten Digit Recognition
🔹 Speech-to-Text Converter
🔹 AI-Powered Calculator
🔹 AI Hangman Game

Intermediate Projects

🔸 AI Virtual Assistant
🔸 Fake News Detector
🔸 Music Genre Classification
🔸 AI Resume Screener
🔸 Style Transfer App
🔸 Real-Time Object Detection
🔸 Chatbot with Memory
🔸 Autocorrect Tool
🔸 Face Recognition Attendance System
🔸 AI Sudoku Solver

Advanced Projects

🔺 AI Stock Predictor
🔺 AI Writer (GPT-based)
🔺 AI-powered Resume Builder
🔺 Deepfake Generator
🔺 AI Lawyer Assistant
🔺 AI-Powered Medical Diagnosis
🔺 AI-based Game Bot
🔺 Custom Voice Cloning
🔺 Multi-modal AI App
🔺 AI Research Paper Summarizer

@datascience_bds
  • ❤ 8
Post #1303 1.6K
ETL Process For Data Analytics
  • ❤ 5
Post #1302 1.63K
✅ The Most Underrated Habit in Data Science

👉 Keep a modeling journal.

After every experiment, write down:

• What changed
• Why you changed it
• The metric before
• The metric after
• What you learned

Six months later, this notebook becomes more valuable than your code.
  • ❤ 10
Post #1300 1.73K
Power BI vs Microsoft Fabric
  • ❤ 5
  • 👍 2
Post #1299 1.72K
🚩7 Red Flags You Should Check in Every Dataset

Before EDA, look for these.

🔻Duplicate rows
🔻Missing values that aren't random
🔻Impossible numbers (negative ages, future dates)
🔻Columns with only one value
🔻Categories with inconsistent spelling
🔻Target leakage
🔻Suspiciously perfect distributions

Catching these early saves hours of debugging later.
  • ❤ 9
Post #1297 1.81K
🧠 LLM Wiki

LLM Wiki is a concept by Andrej Karpathy for maintaining a continuously evolving Markdown knowledge base instead of relying only on document retrieval. As information is processed, related topics are organized into linked wiki pages, making knowledge easier to navigate, update, and reuse over time.

This is a thoughtful read if you're interested in how long-term knowledge systems for LLMs could evolve.

🔗 https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f
Gist llm-wiki llm-wiki. GitHub Gist: instantly share code, notes, and snippets.
  • ❤ 4
Post #1295 1.76K
🔥 Land Your Dream Job – Free Interview Prep Resources Inside!

🌈Struggling with tough interview questions? Nervous about technical grilling? You're not alone.

We've just released a bunch of 100% free interview prep kits for 2026 – covering common Q&As, behavioral questions, technical deep-dives, and role-specific tips for #Cisco, #AWS, #PMP, #AI, #Python, #Excel, and #Cybersecurity.

💥No signup traps, no hidden fees – just click and download.

🎯 Interview Question Bank →
https://bit.ly/4haQJDF
🪜 Online FREE Course → https://bit.ly/4h5CWy6
☁️ FREE AI Materials → https://bit.ly/3U9irqB
📊 Cloud Study Guide → https://bit.ly/4w6WF4j
🧠 Free Mock Exam → https://bit.ly/4w4ffdq

Tag a friend who's also job-hunting – Ace together! 💪

🌐 Join the community: https://chat.whatsapp.com/DcpVeYSV6xNJzdBQU9eRyU
📲 Need personalized help? → https://wa.link/84appq
  • ❤ 5
Post #1294 1.52K
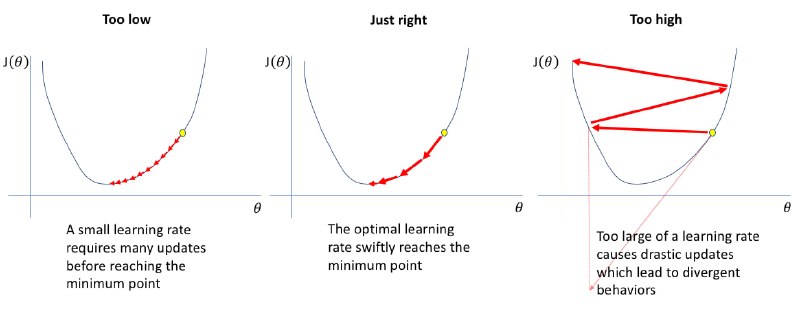
Why Learning Rate Can Make or Break Training

Think of gradient descent as walking downhill. The learning rate controls your step size.

Too small? You'll eventually reach the bottom. It just takes forever.
Too large? You'll keep overshooting the minimum.

Sometimes you'll bounce back and forth without ever converging.
That's why training loss can suddenly explode.

Not because your model is bad.
Because your optimizer is taking steps that are simply too big. The goal isn't the fastest movement. It's stable progress.

👉 Takeaway: When loss behaves unpredictably, learning rate should be one of the first things you investigate.
  • ❤ 5
Post #1292 1.77K
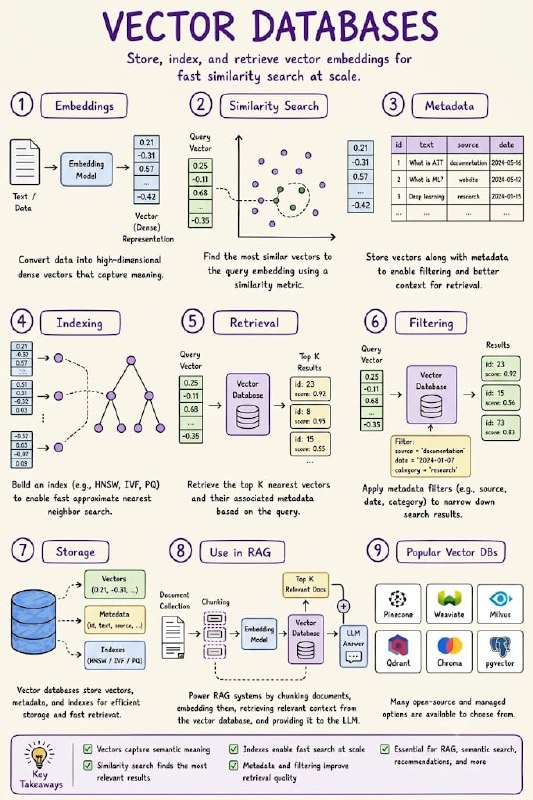
Vector Databases
  • ❤ 8
Post #1291 1.67K

Forwarded from Cool GitHub repositories

superset

Superset is a modern data exploration and data visualization platform. It provides A no-code interface for building charts quickly, A powerful, web-based SQL Editor for advanced querying, A wide array of beautiful visualizations to showcase your data, Highly extensible security roles and authentication options, An API for programmatic customization, and so much more.

Creator: apache
Stars ⭐️: 73,475
Forked by: 17,699

Github Repo:
https://github.com/apache/superset

➖➖➖➖➖➖➖➖➖➖➖➖➖➖
Join @github_repositories_bds for more cool repositories. This channel belongs to @bigdataspecialist group
GitHub GitHub - apache/superset: Apache Superset is a Data Visualization and Data Exploration Platform Apache Superset is a Data Visualization and Data Exploration Platform - apache/superset
  • ❤ 6
Post #1289 1.8K
❔Why Batch Normalization Makes Deep Networks Easier to Train

Training a deep network is a bit like passing a message through twenty people. If each person changes the message slightly, by the end it's completely different.

The same thing happens inside neural networks.

As earlier layers update, the distribution of values reaching later layers keeps changing.
Every layer has to constantly readjust.

Batch Normalization reduces this problem by normalizing each mini-batch during training.
That gives later layers a more stable input distribution.

✅ The result?
• Faster convergence
• Higher learning rates
• Less sensitivity to initialization
• Better training stability
  • ❤ 7
Post #1288 1.6K
✅ Before Building Any Model, Answer These 5 Questions

A surprising number of ML projects fail before training even begins.

Before writing a single line of code, answer these:

1. What decision will this prediction help someone make?
2. What data won't exist when this model is deployed?
3. What's the cost of a wrong prediction?
4. Which metric actually reflects that cost?
5. How will success be measured six months from now?

Most modeling mistakes start here, not in the code.
  • ❤ 5
  • 🔥 1
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →