
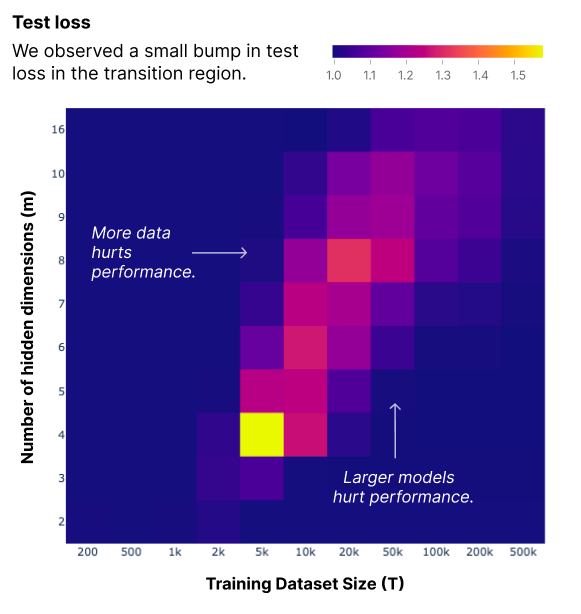
Models struggle to transition between these strategies, as exhibited by a spike in test loss. This spike moves to larger datasets as one increases model capacity. This is a clear signature of double-descent, a phenomenon that is now well-known in the ML literature.
We hope these results are a step towards a mechanistic theory of memorization. There are many open questions, such as understanding the loss spike, or what happens when only a subset of the data is repeated.
Thanks to Adam Jermyn for his comments reproducing and extending these results!
https://transformer-circuits.pub/2023/toy-double-descent/index.html#comment-jermyn-1
Post #7
8.25K
- ❤ 2
- 👍 2
- 👏 2
- 🙏 2
- 😁 1
- 😍 1
- 🤝 1