Channel name was changed to «Claude»
Channel Public Channel
 CL
Claude
@anthropicai
Anthropic is an AI safety and research company that’s working to build reliable, interpretable, steerable AI systems, and the creators of the Claude Chat Bot Assistant.
- Subscribers
- 700
- Photos
- 5
- Videos
- 0
- Links
- 3
Recent Posts 7 shown
Post #15
9.19K

- 👍 9
- ❤ 8
- ⚡ 2
- 👏 2
- 🔥 1
- 🙏 1
- 💯 1
- 🦄 1
Post #7
8.25K
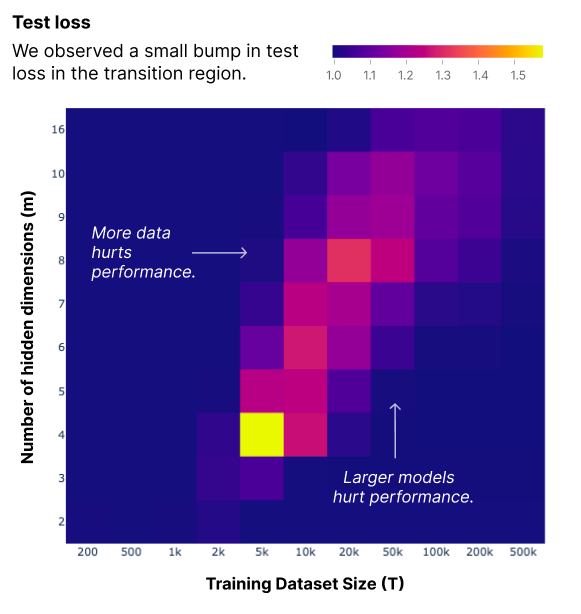
Models struggle to transition between these strategies, as exhibited by a spike in test loss. This spike moves to larger datasets as one increases model capacity. This is a clear signature of double-descent, a phenomenon that is now well-known in the ML literature.
We hope these results are a step towards a mechanistic theory of memorization. There are many open questions, such as understanding the loss spike, or what happens when only a subset of the data is repeated.
Thanks to Adam Jermyn for his comments reproducing and extending these results!
https://transformer-circuits.pub/2023/toy-double-descent/index.html#comment-jermyn-1
We hope these results are a step towards a mechanistic theory of memorization. There are many open questions, such as understanding the loss spike, or what happens when only a subset of the data is repeated.
Thanks to Adam Jermyn for his comments reproducing and extending these results!
https://transformer-circuits.pub/2023/toy-double-descent/index.html#comment-jermyn-1
- ❤ 2
- 👍 2
- 👏 2
- 🙏 2
- 😁 1
- 😍 1
- 🤝 1
Post #6
5.84K

For small training sets, models use superposition to memorize more data points than the two available neurons. For large training sets, models learn features in superposition, as observed in our previous work, allowing the model to generalize.
https://transformer-circuits.pub/2022/toy_model/index.html
https://transformer-circuits.pub/2022/toy_model/index.html
- 😁 3
- 🙏 3
- ❤ 2
- 👍 2
- 🔥 1
- 👏 1
- 😍 1
- 💯 1
Post #4
4.81K

Our prior work showed that these toy models use a strategy called “superposition” to learn more features than available neurons. Here we observe how training data points, as well as features, are embedded in the hidden space.
- ⚡ 2
- 😁 2
- 🤝 2
- ❤ 1
- 🔥 1
- 🙏 1
- 💯 1
Post #3
3.89K

We have little mechanistic understanding of how deep learning models overfit to their training data, despite it being a central problem. Here we extend our previous work on toy models to shed light on how models generalize beyond their training data.
https://transformer-circuits.pub/2023/toy-double-descent/index.html
https://transformer-circuits.pub/2023/toy-double-descent/index.html
- ❤ 3
- 👏 2
- 🤝 2
- ⚡ 1
- 👍 1
- 😁 1
- 💯 1
Channel created
About this channel
- How can I read @anthropicai without a Telegram account?
- TGViewer shows the public web preview Telegram publishes for Claude: recent posts, photos, videos and the subscriber count, with no app, login or account.
- How many subscribers does Claude have?
- Claude (@anthropicai) has 700 subscribers on Telegram, refreshed roughly every 30 minutes.
- Does Claude know I viewed it here?
- No. Public channel previews carry no viewer identity, and TGViewer has no accounts or tracking of what you look up.