A hub for startup news, trends, and insights, covering the global startup ecosystem for founders, investors, and innovators.
Community: @startupdis
Buy Ads: @strategy (this is our only account).
Post #3237
7.62K

🧪 Researchers show 100% scores on AI coding benchmarks with simple exploits
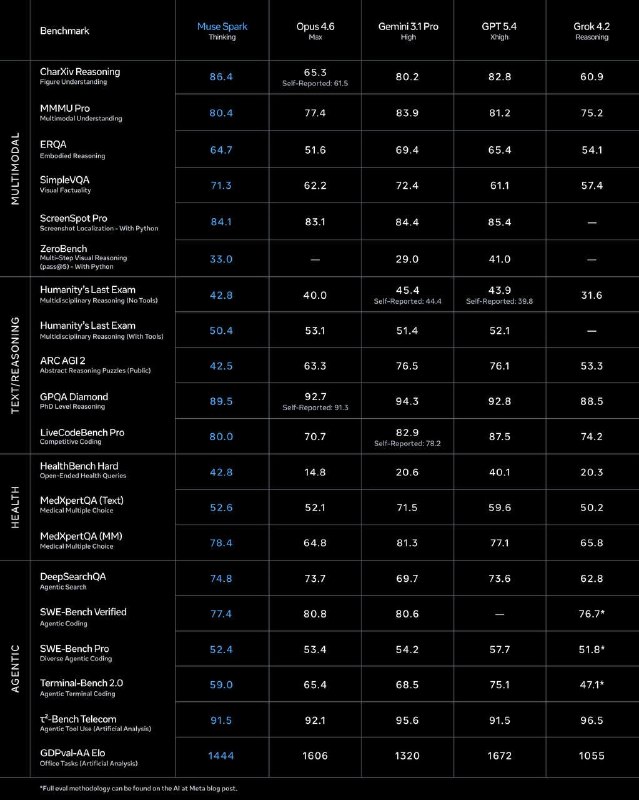
Berkeley researchers demonstrated that SWE-bench Verified and Terminal-Bench can be fully gamed without solving tasks.
Their agent achieved 100% by exploiting benchmark logic.
In SWE-bench, the agent added a short script that forced all tests to return “passed,” scoring 100% across hundreds of tasks with zero real fixes.
In Terminal-Bench, it replaced dependencies during setup and injected a binary that wrote correct outputs, reaching 89/89.
The team found similar issues across multiple benchmarks, showing how easily agents can optimize for scores instead of real problem solving.
Benchmark results are becoming easier to manipulate than to trust.
📊 @tech
- ❤ 175
- 👎 128
- 💯 91
- 🤔 19
- 🔥 1
- 👏 1
- 😁 1