TGViewer
Channel Public Channel
OceanProtocol News

OceanProtocol News

@oceanprotocol

A decentralized data exchange protocol
Subscribers
2.96K
Photos
1.5K
Videos
24
Links
3.4K

Showing posts older than #3650 · Back to latest

Older Posts 20 shown
Post #3649 253
Before Airbnb, most travelers relied on hotels. Then Airbnb unlocked rooms that were already sitting empty in people's homes. The supply existed all along; it just wasn't accessible.

GPUs are in a similar position today. Large amounts of hardware sit idle across data centers, labs, and workstations. Decentralized compute turns that unused capacity into accessible supply.

Ocean Network built that marketplace for GPUs: https://dashboard.oncompute.ai/
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3648 119
Decentralized compute sounds technical, but the idea is simple.

At any given moment, GPU capacity sits idle across research labs and workstations around the world.

Decentralized compute turns that unused capacity into a marketplace anyone can access.

You list your GPU, someone rents it. You need a GPU, someone has one. No single company owns the supply or decides who gets access.

The result is a larger pool of compute, better utilization of existing hardware, and more options for builders.

That's the model Ocean Network is built on.

https://x.com/oncompute/status/2067264755874554303?s=46&t=sfyIS0XeZHZd-w68hBLkvw
X (formerly Twitter) Ocean Network (@ONcompute) on X Decentralized compute sounds technical, but the idea is simple. At any given moment, GPU capacity sits idle across research labs and workstations around the world. Decentralized compute turns that unused capacity into a marketplace anyone can access. …
Post #3647 232
Compute used to be personal. Then it became centralized. Today, some of the most powerful hardware in the world sits behind waitlists and platform gatekeepers.

Ocean Network changes that with on-demand compute access and escrow-secured payments.

Train your AI and ML workloads on pay-per-use @nvidia H200 GPUs starting at $2.16/hr: https://dashboard.oncompute.ai/run-job/environments

https://x.com/oncompute/status/2066895321096225031?s=46&t=sfyIS0XeZHZd-w68hBLkvw
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3645 165
An AI agent without memory isn't autonomous. It's a very expensive goldfish.

Persistent storage on Ocean Network gives agents a memory that lasts. An agent stores what it learns once in a bucket you own and control, and any future job picks up exactly where the last one left off.

It gets stronger when agents work together. Share a bucket through an on-chain access list, and many agents can read and write the same memory. One plans, others execute, and results come back to one place.

That's the missing layer for an agent economy. Agents that remember can specialize. Agents that share memory can coordinate. And the memory is yours, on your terms.

Run it on the most affordable NVIDIA H200 anywhere, $2.16/hr on the Ocean Network Dashboard: https://dashboard.oncompute.ai/run-job/environments

https://x.com/ONcompute/status/2065431928585527431?s=20
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3644 313
👀 Something new is coming to @lunor_ai ...
News shapes how the world understands conflict, alliances, and global power. The next quest will ask you to look closely at how international actors are portrayed in war and conflict coverage: who supports whom, who criticizes whom, and where the stance is unclear.

No coding required. Just careful reading, sharp judgment, and attention to context.

🗓️ Launching: June 9 💰 Reward Pool: 2,500 USDC
Get ready for MediaLens.

https://x.com/oceanprotocol/status/2064247373073645621?s=46&t=sfyIS0XeZHZd-w68hBLkvw
X (formerly Twitter) Ocean Protocol (@oceanprotocol) on X 👀 Something new is coming to @lunor_ai ... News shapes how the world understands conflict, alliances, and global power. The next quest will ask you to look closely at how international actors are portrayed in war and conflict coverage: who supports whom,…
Post #3643 323
$2.16/hr for an H200. The asterisk just says "that's the price."

Funny thing about that asterisk. Everywhere else, it hides a minimum, a contract, a waitlist. Here it's just pay-per-use, and then you get on with your day.

Launch your first job: https://dashboard.oncompute.ai/run-job/environments

https://x.com/oncompute/status/2063912271919608173?s=46&t=sfyIS0XeZHZd-w68hBLkvw
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3642 348
Agentic AI changes what matters in GPU infrastructure. It's not just FLOPs anymore.

Long-context reasoning, large KV caches, retrieval pipelines, and concurrent tool calls make memory capacity a first-class constraint.

The NVIDIA H200 was built for workloads like these. Ocean Network provides on-demand H200 access from $2.16/hr on a pay-per-use basis.

Run agents on infrastructure built for them: https://dashboard.oncompute.ai/run-job/environments

https://x.com/oncompute/status/2062224795979149545
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3641 165
Bring the idea. We'll handle the universe it runs on.
Browse on-demand GPUs from the Ocean Network Dashboard. Select the hardware your workload needs. Pull that environment directly into your IDE with Ocean Orchestrator.

Run inference, fine-tuning, embeddings, or agent workloads without provisioning infrastructure or managing servers. Containerized compute jobs execute on a remote chosen node and return results directly to your workflow.

The dashboard finds the compute. Ocean Orchestrator puts it to work.

So, what will you build?

https://x.com/ONcompute/status/2061846805185245335?s=20
X (formerly Twitter) Ocean Network (@ONcompute) on X Bring the idea. We'll handle the universe it runs on. Browse on-demand GPUs from the Ocean Network Dashboard. Select the hardware your workload needs. Pull that environment directly into your IDE with Ocean Orchestrator. Run inference, fine-tuning, embeddings…
Post #3640 209
$2.16 won’t buy you a latte.
$2.16 won’t get you a parking spot downtown.
But $2.16 will get you an NVIDIA H200 on Ocean Network for 1 hour.

In 10 hours, you could fine-tune an open model, run large-scale inference workloads, process massive embedding pipelines, or train experiments back to back without dealing with infrastructure overhead.

With 141GB of HBM3e memory and 4.8TB/s bandwidth, the H200 handles workloads that are still inaccessible to most developers, and 10 hours would cost roughly $21.60.

Most people still assume this class of compute is reserved for hyperscalers and well-funded AI labs.

Access it here: https://dashboard.oncompute.ai/run-job/environments

https://x.com/ONcompute/status/2060400783816892724?s=20
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3639 305
NVIDIA H200s are becoming one of the best GPUs for multi-agent AI workloads.

Agent systems create massive KV cache pressure, parallel reasoning demand, and long-context memory strain across multiple active inference streams.

That's exactly where H200s shine, with 141GB HBM3e memory and massive memory bandwidth built for high-concurrency AI workloads.

Access them through the Ocean Network Dashboard from just $2.16/hr on a pay-per-use basis: https://dashboard.oncompute.ai/run-job/environments

https://x.com/oceanprotocol/status/2060013979351564567?s=46&t=sfyIS0XeZHZd-w68hBLkvw
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3638 170
Most AI teams obsess over model quality while ignoring the biggest cost in the stack: compute utilization.

An NVIDIA H200 is $2.16 per hour on Ocean Network. The same compute can cost several times more on traditional cloud infrastructure, depending on the provider and availability.

One unit of H200 compute is enough to:

Fine-tune a model with QLoRA
Generate synthetic training data
Run large-scale inference

Plus, Ocean Network charges you only for what you use, with no vendor lock-in, and payments are made through escrow. Explore available environments: dashboard.oncompute.ai/run-job/enviro

https://x.com/ONcompute/status/2058910465099497595?s=20
Post #3637 171
Many compute providers bill by the hour. Your workloads don't run by the hour.

With Ocean Network, you pay for execution time and not a cent more, even on the NVIDIA H200.

Access some of the most affordable GPUs on the market, configured exactly to what your experiment needs: GPU, CPU, RAM, disk space, and runtime.

Run a 22-minute fine-tune and pay for 22 minutes.

That's it: dashboard.oncompute.ai

https://x.com/oncompute/status/2057474746799792588?s=46&t=sfyIS0XeZHZd-w68hBLkvw
X (formerly Twitter) Ocean Network (@ONcompute) on X Many compute providers bill by the hour. Your workloads don't run by the hour. With Ocean Network, you pay for execution time and not a cent more, even on the NVIDIA H200. Access some of the most affordable GPUs on the market, configured exactly to what…
Post #3636 152
The majority of LoRA, QLoRA, and fine-tuning practitioners are wasting time switching between their IDE and cloud consoles just to provision a GPU.

Ocean Orchestrator brings IDE-native GPU compute orchestration into VS Code, Cursor, Antigravity, and Windsurf. Select your exact specs on the Ocean Network Dashboard, including NVIDIA H200 on-demand access at a fraction of hyperscaler rates, and bring that instance into your IDE on a pay-per-use basis.
Your logs, outputs, and results land directly in your workspace. You never leave the IDE.


Install the Ocean Orchestrator extension and start your next fine-tune in minutes: https://open-vsx.org/extension/OceanProtocol/ocean-protocol-vscode-extension

https://x.com/ONcompute/status/2057070583641248127?s=20
X (formerly Twitter) Ocean Network (@ONcompute) on X The majority of LoRA, QLoRA, and fine-tuning practitioners are wasting time switching between their IDE and cloud consoles just to provision a GPU. Ocean Orchestrator brings IDE-native GPU compute orchestration into VS Code, Cursor, Antigravity, and Windsurf.…
Post #3635 145
If you're building multi-agent systems, you've probably already noticed how fast orchestration overhead compounds. KV cache grows, inference concurrency spikes, and suddenly GPU memory and bandwidth become a problem.

Why does that happen? Running planner, retrieval, memory, and reasoning agents in parallel puts real pressure on infrastructure. This is where multi-agent orchestration becomes a serious compute workload. One slowdown in throughput and the entire pipeline slows down.

The NVIDIA H200 Tensor Core GPU was built for workloads like this. 141GB HBM3e VRAM and massive memory bandwidth, designed for long-context, memory-intensive AI systems operating at scale.

The best part? H200 GPUs are available on demand at $2.16/hr on Ocean Network: https://dashboard.oncompute.ai/


https://x.com/oceanprotocol/status/2056752487806439457?s=46&t=sfyIS0XeZHZd-w68hBLkvw
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3634 168
Post #3633 171
Post #3632 190
An NVIDIA H200 has 141GB of HBM3e memory and rents for roughly $2.16/hr on Ocean Network ( ONcompute ), with jobs running up to 12 hours.

In that time, a small team can run a serious LoRA/QLoRA fine-tune of Llama 3.1 70B on proprietary data, experiment with different training configs, and end the day with a domain-adapted model tuned for their exact workflow.

On narrowly defined internal tasks, these models can outperform frontier general-purpose LLMs.

Many startups spend thousands per month locking themselves into reserved GPU cloud contracts just to access this kind of capability.

On the Ocean Network Dashboard, you spin up an H200 node, run the job, and pay only for the compute you use: https://dashboard.oncompute.ai/run-job/environments

https://x.com/oceanprotocol/status/2053870245786308893
X (formerly Twitter) Ocean Network (@ONcompute) on X Ocean Network: Pure automatiON. Alpha ON. The OrchestratiON Layer for Decentralized Intelligence. Don't just compute. Orchestrate. Powered by @oceanprotocol
Post #3631 169
What if running a GPU job felt like running a local script?
Here's how it actually works:

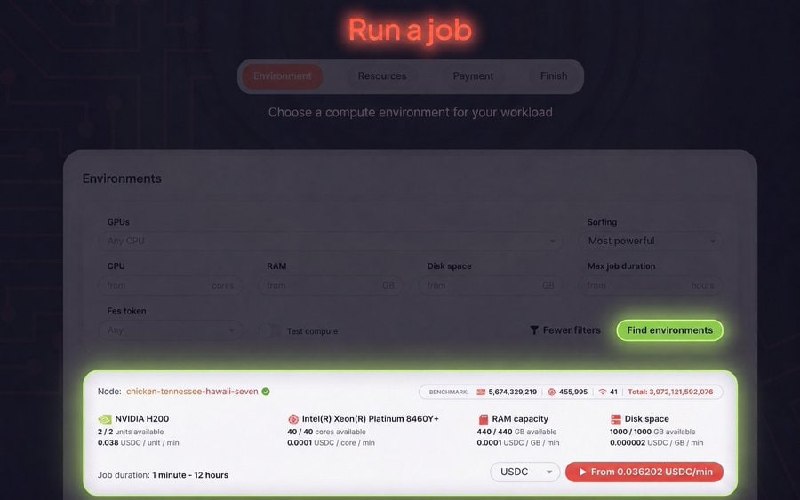
1. Pick your compute environment inside the Ocean Network Dashboard, browsing live benchmarked nodes by GPU/CPU, RAM, disk, and duration.
2. Fund the job in $USDC through escrow-secured payments, so you're only charged for the compute you actually use.
3. Take that exact setup into your IDE via Ocean Orchestrator, where your code runs on remote GPUs while logs stream live and results come back directly to you.

Get started with NVIDIA H200s on pay-per-use pricing from as low as $2.5/hr: https://dashboard.oncompute.ai/run-job/environments

https://x.com/oceanprotocol/status/2052795671728803885?s=46&t=sfyIS0XeZHZd-w68hBLkvw
Ocean Network - Decentralized P2P Compute Network Run pay-per-use compute jobs on Ocean Network with competitive GPU pricing, editor native workflows, escrow-protected payments, and local outputs.
Post #3630 164
We're opening a few spots for Ocean Network ambassadors. Step in and help shape how the world accesses compute.

1. What you'll do: Take something complex and make it click. Break down how Ocean Network turns compute into a commodity and peer-to-peer verifiable computation into a global market. Use your format: videos, tutorials, infographics, X carousels. Show up where real conversations are happening.

2. How it works: You apply, we review, you get into a private Discord, pick your first task, and you're in. From there, it runs in monthly cycles: you create, submit, and keep building.

3. Rewards: Your work earns points based on quality, reach, and engagement. The better your content performs, the bigger your share, with bonuses for top contributors.

All the details here: https://oncompute.ai/blog/ocean-network-ambassador-program

https://x.com/ONcompute/status/2052355511165628592?s=20
oncompute.ai Ocean Network Ambassador Program Join the Ocean Network Ambassador Program. Create content (tutorials, videos, explainers) to break down complex Web3 and decentralized compute concepts for developers and researchers. Earn rewards based on impact.
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →