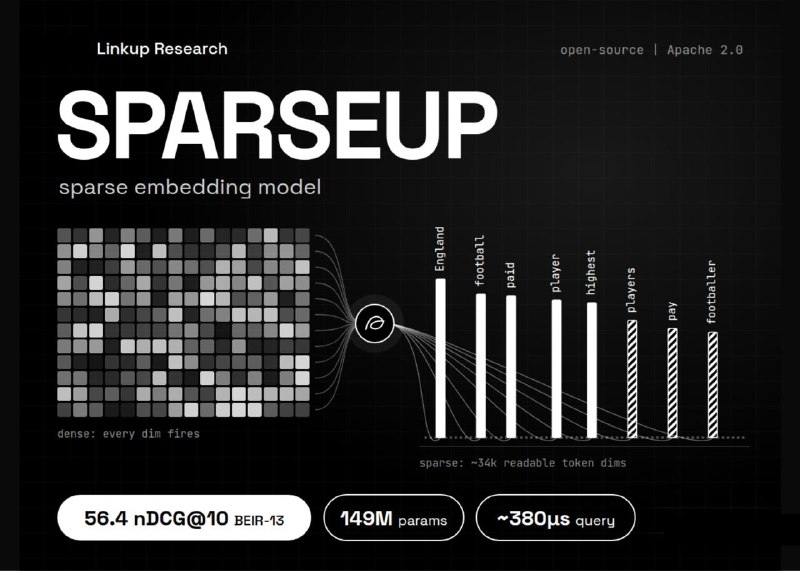
Linkup just open-sourced SPARSEUP, a 149M sparse embedding model scoring 56.4 on BEIR-13.
It is a SPLADE-style retriever that outputs readable token weights, not an opaque dense vector. It fills the sparse slot next to LightOn's DenseOn and LateOn, trained on the same open data.
✅ Apache 2.0, weights on Hugging Face
✅ ModernBERT backbone, English only
✅ 56.4 nDCG@10 on BEIR-13, excluding MS MARCO
✅ Beats splade-v3 (51.7) and opensearch doc-v3-gte (54.6)
✅ ~380µs per query at >97% recall, Seismic, MS MARCO
✅ 47 non-zeros per query, 190 per document
✅ Logit shift of 15 keeps vectors sparse from the start
✅ Top-12 expansion cap per token, not per vector
✅ Case folding cuts output from ~50k to ~34k dims
Every dimension is a token, so you can read exactly why a document matched.
With identical backbone and data, it still trails DenseOn by 1.52 points and LateOn by 2.5. Linkup also documents weak expansions, like number queries spilling into unrelated terms.
Full breakdown: https://www.marktechpost.com/2026/09/19/linkup-research-releases-sparseup/
Model: https://huggingface.co/Linkup-Platform/linkup-sparseup-embed-v1
Technical blog: https://www.linkup.so/blog/introducing-sparseup-by-linkup
Post #1552
794
- ❤ 2