TGViewer
Channel Public Channel
Machine learning books and papers

Machine learning books and papers

@machine_learn

Admin: @Raminmousa1
ID: @Machine_learn
link: https://t.me/Machine_learn
Subscribers
24.2K
Photos
1.1K
Videos
60
Links
1.5K

Showing posts older than #3632 · Back to latest

Older Posts 20 shown
Post #3625 3.58K
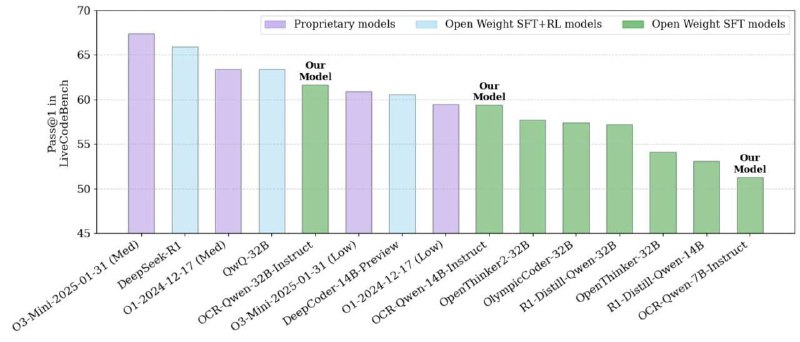
NVIDIA just open sourced Open Code Reasoning models - 32B, 14B AND 7B - APACHE 2.0 licensed 🔥

> Beats O3 mini & O1 (low) on LiveCodeBench 😍

Backed by OCR dataset the models are 30% token efficient than other equivalent Reasoning models

Works with llama.cpp, vLLM, transformers, TGI and more - check them out today!!

https://huggingface.co/nvidia/OpenCodeReasoning-Nemotron-32B

@Machine_learn
  • 👍 10
Post #3622 3.75K

Forwarded from Papers

با عرض سلام
از اين مقاله نفرات ٤ و ٥ باقي مونده دوستاني كه مايل به همكاري هستن لطفا با بنده در ارتباط باشن.


یکی از ابزارهای خوبی که بنده تونستم توسعه بدم ابزار Stock Ai می باشد. در این ابزار از ۳۶۰ اندیکاتور استفاده کردم. گزارشات back test این ابزار در ویدیو های زیر موجود می باشد.

May 2024 :

https://youtu.be/aSS99lynMFQ?si=QSk8VVKhLqO_2Qi3

July 2014:

https://youtu.be/ThyZ0mZwsGk?si=FKPK7Hkz-mRx-752&t=209


@Raminmousa
YouTube May 2024 Backtest Smart AI Signal Telegram Channel #telegram_to_mt4 #telegramsignals ------------------------------------------------------------------------------------- For the next 30 days, you can USE PROMO CODE LAUNCH70 to get 70% off your subscription of the mltiplai.com database. FOR MORE INFO VISIT US AT ✅ https://mltiplai.com ✅…
  • 👍 2
  • ❤ 1
Post #3621 3.35K
⛽ VoRA: Vision as LoRA ⛽
#ByteDance introduces #VoRA (Vision as #LoRA) — a novel framework that transforms #LLMs into Multimodal Large Language Models (MLLMs) by integrating vision-specific LoRA layers.
All training data, source code, and model weights are openly available!

Key Resources:
Overview: https://t.ly/guNVN
Paper: arxiv.org/pdf/2503.20680
GitHub Repo: github.com/Hon-Wong/VoRA
Project Page: georgeluimmortal.github.io/vora-homepage.github.io

@Machine_learn
  • 👍 2
Post #3620 3.2K
Data-engineer-handbook

This is a repo with links to everything you'd ever want to learn about data engineering

Creator: DataExpert-io
Stars ⭐️: 24.9k
Forked by: 4.9k

Github Repo:
https://github.com/DataExpert-io/data-engineer-handbook

#github
➖➖➖➖➖➖➖➖➖➖➖➖➖➖
@Machine_learn
GitHub GitHub - DataExpert-io/data-engineer-handbook: This is a repo with links to everything you'd ever want to learn about data engineering This is a repo with links to everything you'd ever want to learn about data engineering - DataExpert-io/data-engineer-handbook
  • ❤ 2
Post #3618 4.41K
با عرض سلام دوره ی خصوصی SYFA را داریم برگذار میکنیم که هدف نحوه اشنایی با فرایند نگارش و چاپ مقالات می باشد. جلسات ۱ ساعته و خصوصی می باشند. که هر هفته به ازای هر شخص ۲ جلسه برگذار خواهد شد. جهت ثبت نام و ست کردن زمان با ایدی بنده در ارتباط باشین.

@Raminmousa
Post #3614
Machine learning books and papers pinned «با عرض سلام برای یکی از مقالاتمون نیازمند نفر اول داریم که co-author مقاله هم باشه. مجله ی ارسالی scientific report natue https://www.nature.com/srep/ می باشد. شرایط واگذاری رو در صورت نیاز می تونین با ایدی بنده ست کنین. @Raminmousa @Machine_learn…»
Post #3613 3.38K

Forwarded from Papers

با عرض سلام برای یکی از مقالاتمون نیازمند نفر اول داریم که co-author مقاله هم باشه.
مجله ی ارسالی scientific report natue
https://www.nature.com/srep/
می باشد.

شرایط واگذاری رو در صورت نیاز می تونین با ایدی بنده ست کنین.

@Raminmousa
@Machine_learn
@Paper4money
Nature Scientific Reports Scientific Reports publishes original research in all areas of the natural and clinical sciences. We believe that if your research is scientifically valid and ...
  • ❤ 1
  • 👍 1
  • 🥰 1
Post #3612 3.27K
4 advanced attention mechanisms you should know:

• Slim attention — 8× less memory, 5× faster generation by storing only K from KV pairs and recomputing V.

• XAttention — 13.5× speedup on long sequences via "looking" at the sum of values along diagonal lines in the attention matrix.

• Kolmogorov-Arnold Attention, KArAt — Adaptable attention with learnable activation functions using KANs instead of softmax.

• Multi-token attention (MTA) — Lets the model consider groups of nearby words together for smarter long-context handling.

Read the overview of them in our free article on
https://huggingface.co/blog/Kseniase/attentions

@Machine_learn
  • 👍 4
Post #3610 4.28K
هدف اين كانال حل مشكل سايت زني به مقالات. از طرفي كساني كه نيازمند هزينه سايت هستن نيز مي تونن با سايت زدن به هر مقاله ي اين كانال بخشي از هزينه رو دريافت كنن.

https://t.me/papercite
Telegram Paper cite ارسال مقاله جهت سايت @Raminmousa ------ هدف اين كانال حل مشكل سايت زني به مقالات. از طرفي كساني كه نيازمند هزينه سايت هستن نيز مي تونن با سايت زدن به هر مقاله ي اين كانال بخشي از هزينه رو دريافت كنن.
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →