TGViewer
Channel Public Channel
Hugging Face

Hugging Face

@huggingface

Subscribers
303
Photos
1.3K
Videos
408
Links
2.2K

Showing posts older than #2196 · Back to latest

Older Posts 19 shown
Post #2192 59
Hugging Face (Twitter)

RT @Xianbao_QIAN: Want to train your TTS model from scratch with your own cool features?

🎤 Important release for Open-Source SPEECH AI! 🌍

The incredible LEMAS team from IDEA has dropped the dataset they used to train LEMAS, which is also the largest open-source multilingual speech dataset EVER!

150K+ hours across 10 languages with word-level timestamps. They're giving away what most companies would keep locked away forever. 🙏

Two models born from this treasure:
• LEMAS-TTS: Zero-shot multilingual synthesis model
• LEMAS-Edit: Edit speech like you're editing text!!!

Check out this work:
Project home: https://lemas-project.github.io/LEMAS-Project/
Dataset & model released on @huggingface : huggingface.co/LEMAS-Project
Post #2191 29
Hugging Face (Twitter)

RT @Xianbao_QIAN: 2025 is a watershed year for open-source AI. 🚀

It started with DeepSeek R1, followed rapidly by Qwen3, Kimi, and also led to a historic milestone: @Zai_org and @MiniMax_AI became the first LLM companies globally to IPO.

The ecosystem is thriving beyond just the giants:
- Tech & Media: @BaiduResearch, @ByteDanceOSS, @xiaohongshu, @Meituan_LongCat, @ant_oss and @bilibili_en are all making remarkable contributions.
- Finance: More AI teams from quantitative trading firms like IQuest are joining the fray.
- Multimodal: The trend has expanded beyond text to models like @TencentHunyuan 3D, @SkyReels, @Alibaba_Wan, and @Alibaba_Qwen-image.
- Robotics: A huge wave of datasets and models from @XSquareRobot, @UnitreeRobotics, @GalaxeaDynamics, @agibot_research, SpiritAI, and more.
- Datasets: Non-profits like @BAAIBeijing, @OpenMMLab, and IDEA continue to pave the way with impactful open-source data.

This has been a massive year for the...

Перейти на оригинальный пост
Post #2187 40
Hugging Face (Twitter)

RT @Trtd6Trtd: Reachy MiniにWebニュースを読ませてる
アレクサでええやろがい、と言われたらそれまでだが、ちょこちょこ動くのが可愛いので満足
Post #2186 38
Hugging Face (Twitter)

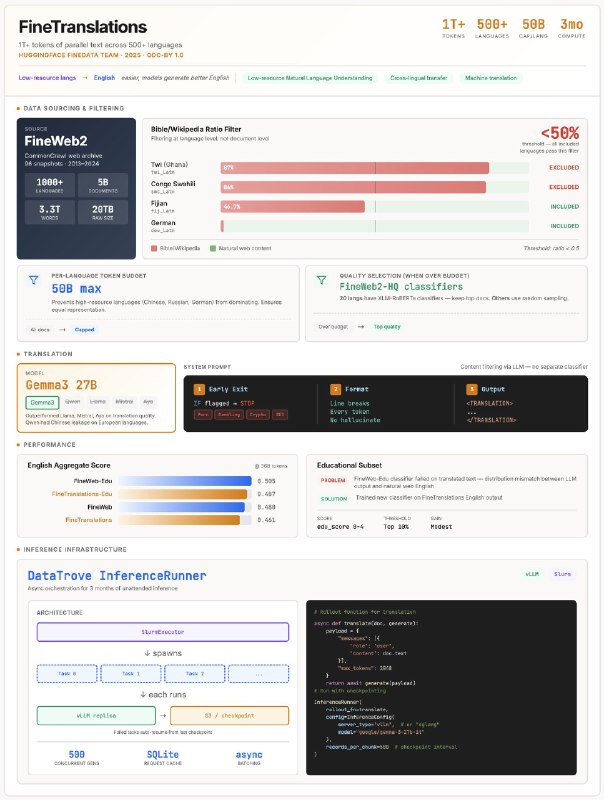
RT @eliebakouch: Most web data in (very) low resource languages is Bible and Wikipedia. The rest? @huggingface data team ran Gemma3 27B for 3 months to translate it into english, to improve translation models and to bring cultural context from 500+ language communities into english training data. Here is the full pipeline

https://huggingface.co/datasets/HuggingFaceFW/finetranslations https://twitter.com/gui_penedo/status/2009677127671492616#m
Post #2185 31
Hugging Face (Twitter)

RT @ben_burtenshaw: TIL: you can scale rl environments as hub spaces to batch sizes of 128 on free hardware! This is ideal for most (humble) RL workloads. Plus, openenv scales from there.

this weekend I'm running a benchmarking experiment on openenv RL environments to see what scale they can reach on the main hardware types: (free/ paid) hub spaces, local docker, local python, and slurm+envoy.

the idea is to have a single env definition (openenv) which takes us from hacker scale to hyper scale, without the env getting in the way.

we're sharing this in detail on wednesday in GPU-Mode
Post #2179 27
Hugging Face (Twitter)

RT @Basilakis: I am so impressed of using Inference Endpoints from @huggingface . So easy to use, so amazing results. The stuff you can get are dope. Some many other services existing doing this, but the simplicity of repo2inference is so easy, that you wonder why to test anything else.
Post #2178 29
Hugging Face (Twitter)

RT @SOSOHAJALAB: Do you guys still cook somethings yourself?
Claudecode with plugins @huggingface doing this automatically but also, make the datasets and upload to HF itself.
How fantastic lovely simply cooking via claude code 👍
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →