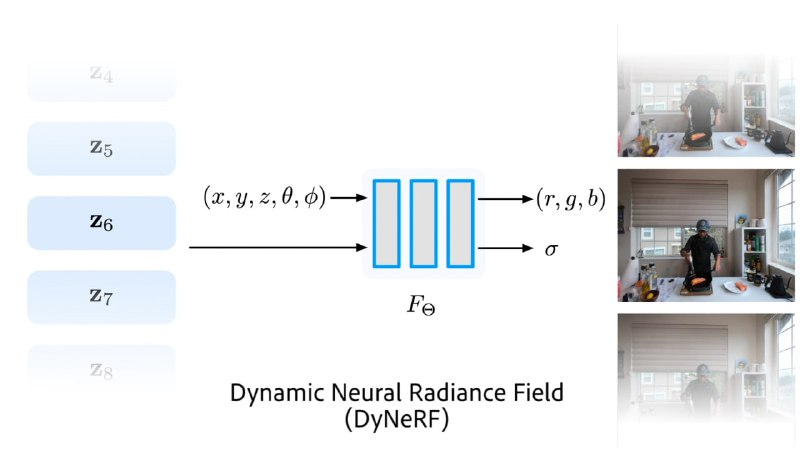
z_t is a time-variant learnable 1024-dimensional latent code. The rest is almost the same as in NERF.🔪 Limitations:
- Training requires time-synchronized input videos from multiple static cameras with known intrinsic and extrinsic parameters.
- Training for a single 10-seconds video is still quite slow for any real-life application: It takes about a week with 8 x V100 GPUs (~1300 GPU hours).
- Blur in the moving regions in highly dynamic scenes with large and fast motions.
- Apparent artifacts when rendering from viewpoints beyond the bounds of the training views (baseline NERF model has the same problems).