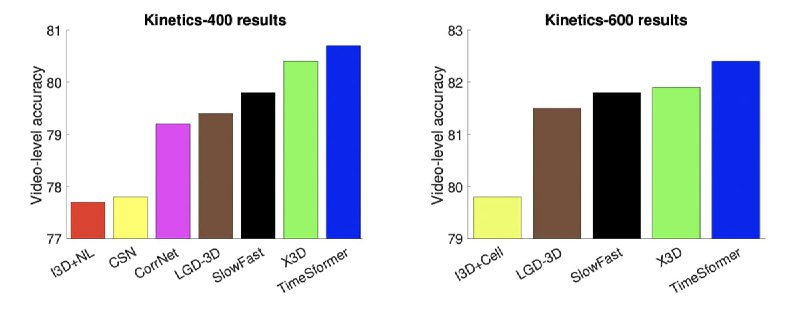
Facebook AI has built TimeSformer, a new architecture for video understanding. It’s the first based exclusively on the self-attention mechanism used in Transformers. It outperforms the state of the art while being more efficient than 3D ConvNets for video.
❓Why it matters
To train video-understanding models, the best 3D CNNs today can only use video segments that are a few seconds long. With TimeSformer, we are able to train on far longer video clips — up to several minutes long. This may dramatically advance research to teach machines to understand complex long-form actions in videos, which is an important step for many AI applications geared toward human behavior understanding (e.g., an AI assistant).
Furthermore, the low inference cost of TimeSformer is an important step toward supporting future real-time video processing applications, such as AR/VR, or intelligent assistants that provide services based on video taken from wearable cameras.
🌐 FAIR Blog
📝 Paper
Post #171
630