Barlow Twins: Self-Supervised Learning via Redundancy Reduction
Yann LeCun, FAIR
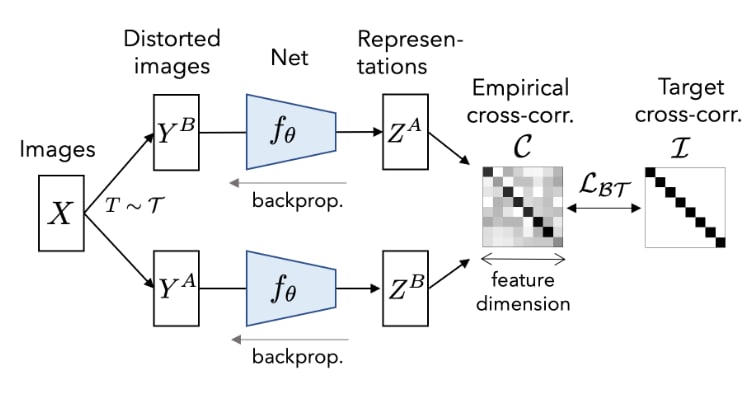
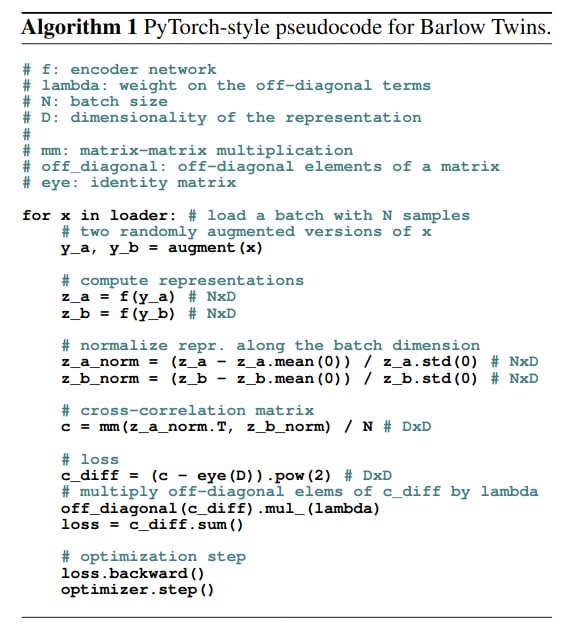
New self-supervised learning loss: compute cross-correlation matrix between the features of two distorted versions of a sample and make it as close to the identity matrix as possible.
+ This naturally avoids representation collapse and causes the representation vectors of distorted versions of a sample to be similar, while minimizing the redundancy between the components of these vectors.
+ It is also robust to the training batch size.
+ Comparable to SOTA self-supervised methods (similar results as BYOL), but the method is conceptually simpler.
⚙️ My favorite part, training resources: 32x V100 GPUs, approx. 124 hours
📝 Paper
🛠 Code (will be released soon)
Post #108
1.45K