Post #2282
10
Channel Public Channel
 FO
- Subscribers
- 196
- Photos
- 29
- Videos
- 3
- Links
- 767
Recent Posts 20 shown
Post #2281
30
Post #2280
58
#llm #vlm #rl #risk_management #abstention
CAP: Conformalized Abstention Policies for
Context-Adaptive Risk Management for LLMs and VLMs
https://openreview.net/pdf?id=DA1ELJTudh
CAP: Conformalized Abstention Policies for
Context-Adaptive Risk Management for LLMs and VLMs
https://openreview.net/pdf?id=DA1ELJTudh
Post #2279
83
#survival_rl
Survival Reinforcement Learning: Toward Scalable Self-Supervised RL
https://arxiv.org/pdf/2605.31273
Survival Reinforcement Learning: Toward Scalable Self-Supervised RL
https://arxiv.org/pdf/2605.31273
Post #2278
91
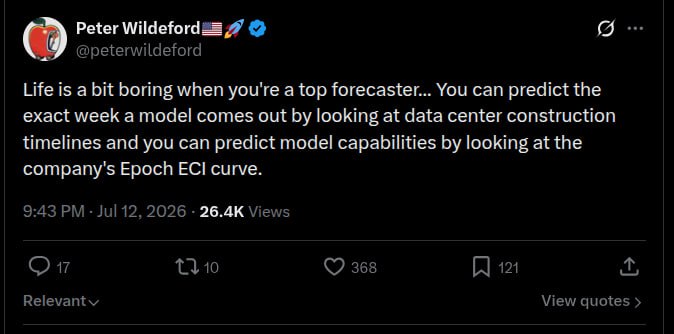
https://x.com/peterwildeford/status/2076391896033980486 #forecast #acx #prediction #contest
Post #2276
110
#edl #llm #ood
Uncertainty Calibration in Deep Learning: Methods, Emerging Challenges, and LLM Frontiers
https://link.springer.com/article/10.1007/s11390-026-6426-z
Uncertainty Calibration in Deep Learning: Methods, Emerging Challenges, and LLM Frontiers
https://link.springer.com/article/10.1007/s11390-026-6426-z
Post #2275
89

Post #2274
94
#meta_learning #pb2 #rl
Meta-learning Population-based Methods for Reinforcement Learning
https://openreview.net/forum?id=d9htascfP8
Abstract: Reinforcement learning (RL) algorithms are highly sensitive to their hyperparameter settings. Recently, numerous methods have been proposed to dynamically optimize these hyperparameters. One prominent approach is Population-Based Bandits (PB2), which uses time-varying Gaussian processes (GP) to dynamically optimize hyperparameters with a population of parallel agents. Despite its strong overall performance, PB2 experiences slow starts due to the GP initially lacking sufficient information. To mitigate this issue, we propose four different methods that utilize meta-data from various environments. These approaches are novel in that they adapt meta-learning methods to accommodate the time-varying setting. Among these approaches, MultiTaskPB2, which uses meta-learning for the surrogate model, stands out as the most promising approach. It outperforms PB2 and other baselines in both anytime and final performance across two RL environment families.
Submission Length: Long submission (more than 12 pages of main content)
Code: https://github.com/automl/MetaPB2
Assigned Action Editor: Mirco Mutti
Submission Number: 3679
Accepted by TMLR
Meta-learning Population-based Methods for Reinforcement Learning
https://openreview.net/forum?id=d9htascfP8
Abstract: Reinforcement learning (RL) algorithms are highly sensitive to their hyperparameter settings. Recently, numerous methods have been proposed to dynamically optimize these hyperparameters. One prominent approach is Population-Based Bandits (PB2), which uses time-varying Gaussian processes (GP) to dynamically optimize hyperparameters with a population of parallel agents. Despite its strong overall performance, PB2 experiences slow starts due to the GP initially lacking sufficient information. To mitigate this issue, we propose four different methods that utilize meta-data from various environments. These approaches are novel in that they adapt meta-learning methods to accommodate the time-varying setting. Among these approaches, MultiTaskPB2, which uses meta-learning for the surrogate model, stands out as the most promising approach. It outperforms PB2 and other baselines in both anytime and final performance across two RL environment families.
Submission Length: Long submission (more than 12 pages of main content)
Code: https://github.com/automl/MetaPB2
Assigned Action Editor: Mirco Mutti
Submission Number: 3679
Accepted by TMLR

Post #2273
84
KANFormer for Predicting Fill Probabilities via Survival Analysis in Limit Order Books
#kan #transformer #shap #c_index #cac_40 #lob
https://arxiv.org/pdf/2512.05734
#kan #transformer #shap #c_index #cac_40 #lob
https://arxiv.org/pdf/2512.05734
Post #2272
88
#agi #ex #google #chollet #team #atari2600 #atari
https://arcprize.org/arc-agi/3/
https://arcprize.org/arc-agi/3/
Post #2271
87
#a16z #team #elon_mask #space #hyper #hyperscalers #ai #forecast
https://x.com/elonmusk/status/2021564364483080329
#surv #cox #deephit #deepsurv #kan
SurvKAN: A Fully Parametric Survival Model Based on Kolmogorov–Arnold Networks
https://arxiv.org/pdf/2602.02179
X (formerly Twitter) Elon Musk (@elonmusk) on X RT @a16z: Elon Musk on scaling AI in space: Earth is the bottleneck.
"It’s harder to scale on the ground than it is to scale in space."
"… https://x.com/elonmusk/status/2021564364483080329
#surv #cox #deephit #deepsurv #kan
SurvKAN: A Fully Parametric Survival Model Based on Kolmogorov–Arnold Networks
https://arxiv.org/pdf/2602.02179
Post #2269
107
#llm #chess #arc_agi_3 #arc_agi #reasoning #agi
https://openreview.net/forum?id=65R1Dbfwzk
openreview.net LLM CHESS: Benchmarking Reasoning and Instruction-Following in LLMs... We introduce LLM CHESS, an evaluation framework designed to probe the generalization of reasoning and instruction-following abilities in large language models (LLMs) through extended agentic... https://openreview.net/forum?id=65R1Dbfwzk
Post #2268
123
#nvidia #team
NVARC solution to ARC-AGI-2 2025
https://drive.google.com/file/d/1vkEluaaJTzaZiJL69TkZovJUkPSDH5Xc/view
#LLM #fintech #Benchmark #deepseek #claude #minimax #qwen #gemini
AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets
https://arxiv.org/abs/2512.10971
NVARC solution to ARC-AGI-2 2025
https://drive.google.com/file/d/1vkEluaaJTzaZiJL69TkZovJUkPSDH5Xc/view
#LLM #fintech #Benchmark #deepseek #claude #minimax #qwen #gemini
AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets
https://arxiv.org/abs/2512.10971
Post #2267
159
#quantum #photonic #ai #scalable #cloud #compute #nvidia
https://thequantuminsider.com/2025/11/15/chinas-new-photonic-quantum-chip-promises-1000-fold-gains-for-complex-computing-tasks/
https://thequantuminsider.com/2025/11/15/chinas-new-photonic-quantum-chip-promises-1000-fold-gains-for-complex-computing-tasks/

Post #2266
118
Post #2265
130
#llm #web_articles #statistics #graphite_io #team
https://x.com/Mayhem4Markets/status/1981699049322635576
X (formerly Twitter) Markets & Mayhem (@Mayhem4Markets) on X The rise of AI-generated content over time https://x.com/Mayhem4Markets/status/1981699049322635576
Post #2264
139
#arc_agi #agi
Less is More: Recursive Reasoning with Tiny Networks
https://arxiv.org/abs/2510.04871v1
Discovering New Theorems via LLMs with In-Context Proof Learning in Lean
https://arxiv.org/abs/2509.14274
arXiv.org Less is More: Recursive Reasoning with Tiny Networks Hierarchical Reasoning Model (HRM) is a novel approach using two small neural networks recursing at different frequencies. This biologically inspired method beats Large Language models (LLMs) on... Less is More: Recursive Reasoning with Tiny Networks
https://arxiv.org/abs/2510.04871v1
Discovering New Theorems via LLMs with In-Context Proof Learning in Lean
https://arxiv.org/abs/2509.14274
Post #2263
124
#grpo #vs #dpo #reinforcement_learning #rl #llm #qwen
It Takes Two: Your GRPO Is Secretly DPO
https://arxiv.org/abs/2510.00977
#benchmark #timeseries #msIC #msIR #kaggle #btcf #btc #gsmi #options #sota #CSI #etf #AAAI #NeurIPS #openreview #ICRL
FinTSBridge: A New Evaluation Suite for Real-world Financial Prediction with Advanced Time Series Models
https://openreview.net/forum?id=6UHEfOBVkn
arXiv.org It Takes Two: Your GRPO Is Secretly DPO GRPO has emerged as a prominent reinforcement learning algorithm for post-training LLMs. Unlike critic-based methods, GRPO computes advantages by estimating the \emph{value baselines} from... It Takes Two: Your GRPO Is Secretly DPO
https://arxiv.org/abs/2510.00977
#benchmark #timeseries #msIC #msIR #kaggle #btcf #btc #gsmi #options #sota #CSI #etf #AAAI #NeurIPS #openreview #ICRL
FinTSBridge: A New Evaluation Suite for Real-world Financial Prediction with Advanced Time Series Models
https://openreview.net/forum?id=6UHEfOBVkn
Post #2262
120
#perspective #the_economist #team #ai #investment #bubble ?
https://www.economist.com/leaders/2025/09/11/what-if-the-3trn-ai-investment-boom-goes-wrong
#microsoft #team #agentic #llm #fintech #quant
R&D-Agent-Quant: A Multi-Agent Framework for Data-Centric Factors and Model Joint Optimization
https://arxiv.org/abs/2505.15155
https://github.com/microsoft/RD-Agent?tab=readme-ov-file
https://www.economist.com/leaders/2025/09/11/what-if-the-3trn-ai-investment-boom-goes-wrong
#microsoft #team #agentic #llm #fintech #quant
R&D-Agent-Quant: A Multi-Agent Framework for Data-Centric Factors and Model Joint Optimization
https://arxiv.org/abs/2505.15155
https://github.com/microsoft/RD-Agent?tab=readme-ov-file

Post #2261
106
#abtest #rct #fda #approved #genetics #mit #harvard ( George Church ) #team #kidney
https://egenesisbio.com/press-releases/egenesis-announces-ind-clearance-for-egen-2784-in-kidney-transplant-and-landmark-patient-updates-in-ongoing-expanded-access-study/
https://egenesisbio.com/press-releases/egenesis-announces-ind-clearance-for-egen-2784-in-kidney-transplant-and-landmark-patient-updates-in-ongoing-expanded-access-study/

About this channel
- How can I read @fordevelopers without a Telegram account?
- TGViewer shows the public web preview Telegram publishes for For Developers: recent posts, photos, videos and the subscriber count, with no app, login or account.
- How many subscribers does For Developers have?
- For Developers (@fordevelopers) has 196 subscribers on Telegram, refreshed roughly every 30 minutes.
- Does For Developers know I viewed it here?
- No. Public channel previews carry no viewer identity, and TGViewer has no accounts or tracking of what you look up.