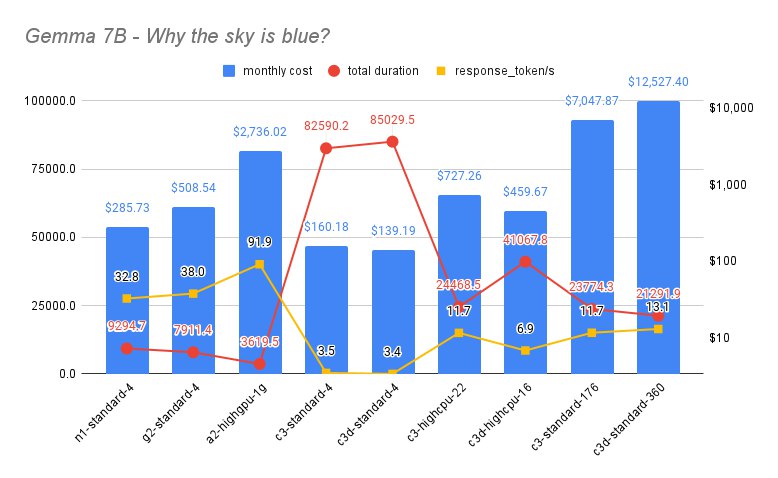
This blogpost explores the deployment of large language models (LLMs) using a combination of Google Kubernetes Engine (GKE), Google Gemma, and the Ollama framework, highlighting the benefits of customization, flexibility, and cost-effectiveness. By leveraging these tools, users can achieve seamless and efficient LLM deployment while maintaining control over their data and environment.
https://medium.com/google-cloud/gke-gemma-ollama-the-power-trio-for-flexible-llm-deployment-5f1fa9223477
Post #2128
2.2K