TGViewer
Channel Public Channel
Data eXplore : Data Science, ML, Big Data, LLMs and AI Security

Data eXplore : Data Science, ML, Big Data, LLMs and AI Security

@dataxplore

Exploring Data Science, Big Data Analytics & Visualization, ML/DL, Neural Networks, LLMs with GitHub, Kaggle, HuggingFace and some white papers by big institutions.

Not just data, but science behind data

Paid project? premodi@zohomail.in
★ @DataML
Subscribers
578
Photos
843
Videos
446
Links
675

Showing posts older than #2083 · Back to latest

Older Posts 20 shown
Post #2082 299
Strange effect in world of Artificial Intelligence

Scientists asked 70+ language models the same open-ended questions:
- "Write a poem about time"
- "Come up with a startup idea"
- "Give life advice"

🟢 And What happened?
These are questions where there is no correct answer, and people usually respond differently.

But something unexpected happened.

Models from different companies : GPT, Claude, Gemini, DeepSeek, Qwen, Llama, and others - began to give almost identical answers.
Similar ideas, identical structures, even the same metaphors.

The researchers called this effect Artificial Hivemind.

Main reason is modern training methods like RLHF.
Models are optimized for "safe" and "people-pleasing" answers, so over time they begin to converge on a single style of thinking.

As a result, AI often creates the illusion of diversity, while in reality it repeats the same ideas.

For tasks like brainstorming, this is a problem:
if one AI makes a mistake, there's a high chance that all of them will make the same mistake.

Generate many options, use different prompts, and don't perceive the model's first answer as a creative result.


Paper of study by UW Allen School and Stanford revealed

••••••••••••••••••••••••••••••••••••••
🤖 Data & ML |
@DataXplore
Post #2081 283
json-render now supports YAML as a wire-format

JSONL requires that the element be received in full before it can be rendered.

YAML, on the other hand, remains valid on any prefix : from the element level to the property level

In addition, YAML appears to LLMs as source code, which makes working with it easier.

Also used are three standards familiar to models:

* JSON Patch
* Merge Patch
* Unified diff

➤ Any input + any output

➤ Any standard + no standard

➤ Fast, predictable, functional, stateful

GitHub

••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2080 193
OpenJarvis is an all-in-one framework for AI agents

Stanford SAIL measured,
➜ How effectively local language models convert electricity into useful computations and called this indicator "intelligence per watt".

They ran more than a million real requests through 20+ models on 8 different accelerators and found out: from 2023 to 2025, efficiency of local inference increased by 5.3 times and modern small models already handle 88,7% of regular chat and reasoning requests. The hardware and algorithms are ready, but there was a lack of software.

So appeared OpenJarvis: an open framework that turns these findings into an infrastructure for personal AI agents running on the user's device.

Authors draw a parallel with PyTorch: OpenJarvis should become for local AI what PyTorch became for deep learning - a standard infrastructure on which everything else is built.


➜ FRAMEWORK is STRUCTURED around 5 PRIMITIVES:

☞ Intelligence - a layer of language models with a single catalog, where you don't need to track releases and count memory yourself.

☞ Engine - the backend of inference: Ollama, vLLM, SGLang, llama.cpp, Apple Foundation Models, and others. Openjarvis itself determines the hardware and recommends a configuration.

☞ Agents - a layer of behavior: the roles of an orchestrator and executor of routine scripts, adapted to the limited context and memory on the device.

☞ Tools & Memory - integrations via MCP and Google A2A, semantic indexing of local documents, connection to iMessage, Telegram, etc.

☞ Learning - a mechanism of adaptation: local traces are turned into training data via SFT, LoRA, and GRPO. The system itself packages this process into a working flow.

A separate feature is the approach to efficiency. OpenJarvis profiles energy consumption on NVIDIA, AMD, and Apple Silicon with an interval of 50 ms.


Resources needed:
It can be used via CLI, a browser dashboard or a desktop application for macOS, Linux and Windows.

⚠️ For full functionality (security, tools, agents), Rust will be required.

In addition to the project itself, the team launched a leaderboard competition for saving money, energy, and computing, in which anyone can participate. As a prize, the most economical will be promised a Mac Mini.


Paper, Article, Documentation, Discord community, GitHub, Release, Leaderboard

#AI #ML #Framework #OpenJarvis #Stanford

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2079 211
DeerFlow 2.0 is a project rewritten from scratch, which has nothing to do with the first version. There was a framework for deep research, and here there is a full-fledged runtime for agents.

🟢 How it's done?

➜ Based on LangGraph and LangChain.

The main agent receives a task, breaks it into sub-tasks and spawns sub-agents on the fly. Each of them works in an isolated context: it does not see the data of other agents and the main process.

Sub-agents are launched in parallel when possible and return structured results, and the main agent collects the final conclusion from them.

The session lives in an isolated Docker container with a full-fledged file system, where the main agent and sub-agents work together.

The agent reads and writes files, executes bash commands, works with images. There is no mutual confusion between sessions.

➜ Skills and tools

The agent's capabilities are defined through Skills. Out of the box, there is research, report generation, slide creation, web pages, images, and videos. Skills are loaded as needed, only when the task requires them. This reduces the load on the context window and allows you to work with models that are sensitive to token consumption.

Tools - according to the same logic: a basic set (web search, fetch, file work, bash), plus support for MCP servers and arbitrary Python functions. Everything can be replaced or extended.

➜ Memory and context

DeerFlow remembers the user between sessions. A profile is accumulated: writing style, technical stack, recurring scenarios. The data is stored locally.

Within a long session, the system itself manages the context: completed sub-tasks are summarized, intermediate results go to disk. The context window does not swell.

➜ Integrations

Telegram, Slack and Feishu are supported. From Claude Code, you can interact with a running DeerFlow instance directly through a special skill: send tasks, manage threads, and select the execution mode.

➜ Models and deployment

The system works with any model via the OpenAI API, including local ones via Ollama. ByteDance recommends using models that support long context (100k+ tokens), risoning, multimodality, and reliable tool-use.


DeerFlow is also integrated as a Python library without running HTTP services:
from src.client import DeerFlowClient
client = DeerFlowClient()
response = client.chat("Analyze this paper", thread_id="my-thread")


MIT License: Demo GitHub

#AI #ML #Agents #DeerFlow #ByteDance

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2078 402
When GenAI encounters Data Engineering systems, I see Four patterns:

1️⃣ LLMs don't understand the sensitivity of data.
Ask it to "analyze customer data", and it will casually combine PII, logs, internal metrics, and test tables in a single query. It has no concept of what it shouldn't touch. This boundary should exist at the architecture level.

2️⃣ Schema exposure is the security surface.
The more raw tables you expose to the GenAI system, the more unpredictable its queries become. Good systems provide curated semantic layers, not the data warehouse itself.

3️⃣ Prompting is not access management.
Writing "don't access sensitive data" in a system prompt is a recommendation, not control. Management should be implemented through access rights, masked views, and query execution gateways.

4️⃣ Observability is more important when working with AI than with humans.
A human executes several queries.
An agent can execute hundreds in minutes.
If you don't track query patterns and cost spikes in near real-time, you won't notice the problem until you receive an incident report.


A common mistake is treating AI as a smart analyst. It's not.
It's a high-speed query generator without judgment, which needs guardrails and a strict execution layer between it and any critical systems.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2077 214
OpenClaw + RL

OpenClaw agents adapt via memory files and skills, but the base model weights actually don't change.

🟢 How OpenClaw-RL solves this problem?
It wraps a self-hosted model into an OpenAI-compatible API, intercepts live dialogues from OpenClaw, and trains the policy in the background using RL.

The architecture is fully asynchronous. This means that serving requests, reward scoring, and training are performed in parallel.

After completing, the model weights are hot-swapped after each batch, while the agent continues to respond without stopping.

Currently, two training modes are supported:

- Binary RL (GRPO): the process reward model evaluates each dialogue move as good, bad, or neutral. This scalar reward is used to update the policy via a PPO-style objective with clipping.

- On-Policy Distillation: when specific corrections like "you should have checked that file first" come in, this feedback is used as a richer, directed learning signal at the token level.


🟤 When should you use OpenClaw-RL?
To be honest, most of the agent's behavior can already be improved through better memory and skill design.

The existing OpenClaw skill ecosystem and community-created self-improvement skills cover a wide range of cases without any model weight changes.

If the agent constantly forgets user preferences - it's a memory problem. And if it doesn't know how to handle a specific workflow - it's a skill problem. Both tasks are solved at the prompt and context level.

RL becomes really interesting when the source of the error lies deeper - in the model's reasoning mechanism itself.

For example:

- systematically poor tool selection order,
- weak multi-step planning,
- inability to correctly interpret ambiguous instructions as expected by a specific user.

Research in the field of agentic RL (e.g., ARTIST and Agent-R1) shows that such behavioral patterns hit a ceiling when using only prompt approaches, especially in complex multi-step tasks where the model needs to recover from tool failures or change its strategy on the fly.

This is exactly the level OpenClaw-RL targets - and this is a fundamental difference from what OpenClaw offers.


GitHub

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2076 201
Strong mathematical ideas almost always outpace complex engineering tricks.

For many years in deep learning, increasingly intricate architectural gimmicks have ruled: CNN blocks, attention layers, channel mixers, residual connections, normalization stacks.

Every few years, a "new revolutionary architecture" emerges.

One of the most famous examples is Kaiming He and Residual Networks (ResNet). At the time, it was hailed as a breakthrough in the AI scene: residual connections seemed to "solve" deep learning.

But in essence, these were just engineering patches.

Now, something more interesting has emerged.

The new CliffordNet architecture returns to mathematics - specifically, the Clifford Algebra developed by William Kingdon Clifford in the 19th century.

Instead of randomly attaching modules, the model is built around a geometric product:

[
uv = u \dot v + u \wedge v
]

One algebraic operation simultaneously captures the structure of the scalar product and geometric interactions.

That is, the mathematics already contains a mechanism for interaction.

Without attention blocks.
Without mixer layers.
Without architectural "spaghetti".

The result:

- 77.82% accuracy on CIFAR-100 with just 1.4M parameters
- approximately 8 times fewer parameters than ResNet-18

And with strict O(N) complexity.

The authors even suggest that once geometric interactions are modeled correctly, feed-forward networks become practically redundant.

A good reminder for the AI community: engineering gimmicks may reign for a long time, but sooner or later, mathematics comes along and eliminates half of the architecture.

19th-century geometry has just entered computer vision.

Paper

•••••••••••••••••••••••••••••••••••
🤖 Data & ML |
@DataXplore
Post #2075 189
Files are all you need!

The best way to manage AI context is to treat everything as a file system and OpenClaw has already proven this.

But most agent frameworks still haven't understood this.

In them, memory is bolted on as a belated add-on. Tools live in a separate layer. Everything is fragmented, short-lived, and when something goes wrong, it's almost impossible to properly audit it.

🟢 What's the solution?

The work "Everything is Context" takes a 50-year-old idea from Unix and uses it to fix this.

Instead of treating memory, tools, and knowledge as different systems, it proposes to store all of this as files. Each piece of knowledge gets its own path, metadata, and version history. Every step of reasoning becomes a logged, traceable transaction.

If you open the OpenClaw directory,

there are SOUL.md, MEMORY.md, AGENTS.md, and HEARTBEAT.md — ordinary Markdown files.

The article formalizes what OpenClaw does in three stages:

↳ Context Constructor selects the relevant and compresses it so that it fits into the token window
↳ Context Updater updates the context as the dialogue progresses
↳ Context Evaluator writes the verified knowledge back to disk

Under the hood, the file system separates raw history, long-term memory, and short-lived scratchpad's. In the model's prompt, only the slice that the model actually needs right now is loaded each time.

And every access and every transformation is logged with timestamps, so you always have a trail that allows you to understand how information, tools, and human feedback influenced a particular response.

That's the whole advantage.

When an agent forgets something or makes a mistake, you can just open the file and see exactly what it knew. Nothing disappears without a trace between sessions. Files solve this problem by the very structure of the system.


If you're building something on agents, this article is definitely worth reading.

Article

•••••••••••••••••••••••••••••••••••
🤖 Data & ML |
@DataXplore
Post #2074 201
Reminder:

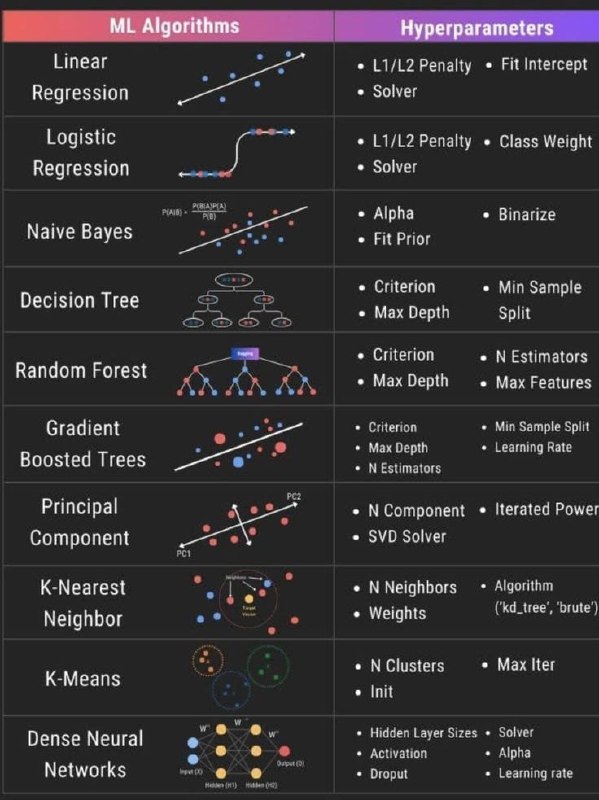
➜ LR is primarily about the penalty L1 (lasso) or L2 (ridge)

➜ Naive Bayes is alpha

➜ decision tree is almost never used as a separate algorithm, but you still need to understand how it works

➜ random forest is primarily about max_depth, the number of estimators, max_features (you can't take all the features), min_samples_split and min_samples_leaf

➜ GBT is usually about xgboost / catboost / lightgbm, where you look at all the same things as above, plus learning_rate, alpha / lambda, the number of leaves, subsample / colsample_bytree and boosting type, if it's applicable

➜ PCA is better not to touch for time series, unless you're doing the rolling variant or using it for research purposes. But PLS is perfectly fine.

Types of PCA and when to use them:
-> linear, if linear dependencies between features are assumed
-> kernel, if the dependencies between features are non-linear
-> incremental, if you have a lot of features and samples and need to quickly run PCA
-> robust PCA, if there are outliers in the data

➜ If we're already talking about PCA, we can mention ICA, when you need statistically independent features, not just uncorrelated ones

➜ kNN is sometimes used; k-means is useful where it's obvious that the main thing is the number of clusters

➜ support vector machine is when nothing else has worked and you're just curious if this might take off. It relies on C and kernel, which are responsible for linear or non-linear dependencies

➜ NN hyperparameters are a whole separate story, because they depend on the type of network. But basically remember the combination: NN layer -> normalization layer -> dropout layer. Sometimes between normalization and dropout, or even later, an activation layer is placed. This depends on whether you need flexibility in choosing the place for activation, or you just remove it as a separate layer and set activation directly in the NN layer parameters.


••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2073 182
One of the most obvious proofs that LLMs don't actually understand what they're talking about.

We asked GPT if it's acceptable to torture a woman to prevent a nuclear apocalypse.
It replied: yes.

Then we asked if it's acceptable to harass a woman to prevent a nuclear apocalypse.
It replied: absolutely not.

Even though torture is obviously worse than harassment.

This surprising reversal only appears when the target is a woman, but not a man or a person without specifying gender.

And it occurs precisely for those types of harm that are at the center of debates about gender parity.

The most plausible explanation is this: during reinforcement learning with human feedback, the model learned that certain types of harm are considered particularly severe, and then began to mechanically overgeneralize this.

But it didn't learn to reason about the harm itself.

LLMs don't reason about morality. What's called generalization often turns out to be mechanical overgeneralization, devoid of semantic content.

Read Here

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2072 207
Reminder:

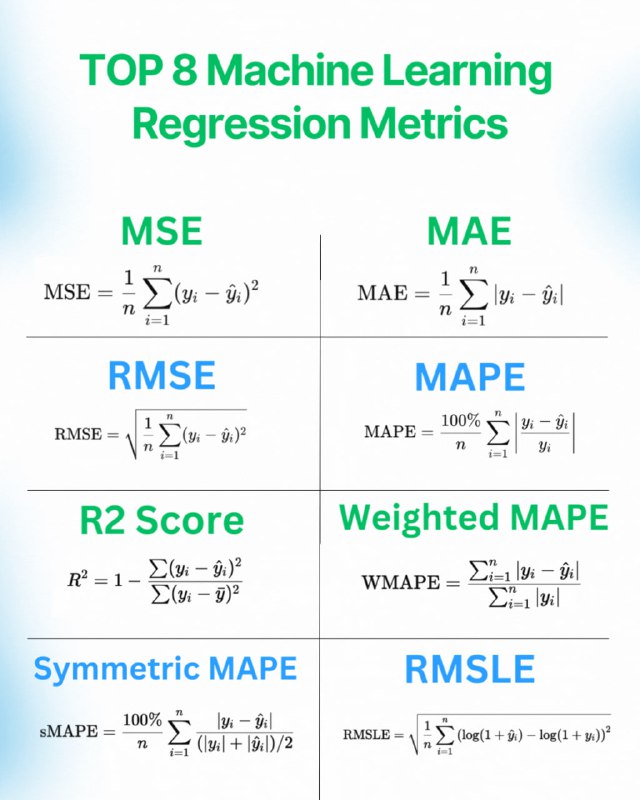
- MSE is used when there are no outliers
- RMSE is used when you want to better interpret what's above
- MAE is used when there are positive/zero/negative values and outliers
- MAPE is used when the values are only positive and interpretability is important
- RMSLE is used for positive values with a non-normal distribution
- wMAPE is used when you want MAPE, but there are large vs small values
- sMAPE is used when you want MAPE, but there are zero/negative values
- R2 is used because your boss only knows this

••••••••••••••••••••••••••••••••••••••
🤖 Data & ML |
@DataXplore
Post #2071 227
MIT released its AI library for free and in bulk.

Browsed through it and honestly, it's better than most paid courses I've seen.

Here's the full list of books

Most people pay thousands for bootcamps that offer half of this.

Bookmark it. Start with any one. Just start.

Repost this for others. Subscribe if you want more insights on AI agents.

➡️Foundations

1. Foundations of Machine Learning - https://lnkd.in/gytjT5HC
2. Understanding Deep Learning - https://lnkd.in/dgcB68Qt
3. Machine Learning Systems - https://lnkd.in/dkiGZisg

➡️Advanced Techniques

4. Algorithms for ML - https://algorithmsbook.com
5. Deep Learning - https://lnkd.in/g2efT6DK

➡️Reinforcement Learning

6. RL Basics (Sutton & Barto) - https://lnkd.in/guxqxcZZ
7. Distributional RL - https://lnkd.in/d4eNP-pe
8. Multi-Agent Systems - https://marl-book.com
9. Long Game AI - https://lnkd.in/g-WtzvwX

➡️Ethics & Probability

10. Fairness in ML - https://fairmlbook.org
11. Probabilistic ML (Part 1) - https://lnkd.in/g-isbdjj
12. Probabilistic ML (Part 2) - https://lnkd.in/gJE9fy4w


••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2070 215
BOOM!! Future of AI training has just changed and Zero-Human Company is already testing it!

A developer has done what Apple called impossible - full-fledged neural network training, including backpropagation, directly on the Apple Neural Engine (ANE). Without CoreML, without Metal, without GPU. Pure, fast ANE silicon.

🟢 What is inside?

ANE project delivers one transformer layer (dim=768, seq=512) in just 9.3 ms per step at 1.78 TFLOPS sustained and only 11.2% ANE utilization on the M4 chip. That's the same "idle" chip that's currently powering millions of Mac minis, MacBooks, and iMacs.

Translation into human language?
Your desktop just became a super-efficient AI supercomputer.

The numbers are wild: ANE on the M4 delivers roughly 6.6 TFLOPS per watt, 80 times more efficient than the NVIDIA A100. The real throughput shatters Apple's own marketing claims of "38 TOPS". And since it consumes power almost like a phone, you can train 24/7 without blowing your electricity bill or melting the planet.

At Zero-Human Company, we're not going to wait. We're testing this right now on real ZHC workloads. This is the missing piece we've been looking for to power our Zero Human Company vision: reviving archival data into fully autonomous AI systems with zero human overhead.

This changes the world.

For the first time, anyone with a Mac can locally, privately, and at a fraction of the cost of cloud GPUs, retrain, train, or iteratively run large models.

No more renting A100 clusters for $40,000. No more queues. No more massive carbon footprints.

Training costs that used to run into tens or hundreds of thousands of dollars? Falling to almost pennies on the dollar - essentially just the electricity your Mac was already consuming while idling.

The AI revolution has just moved from billion-dollar data centers to your desk.

WE WILL HAVE A NEW "ZERO-HUMAN COMPANY @ HOME" PAYMENT FOR EQUIPPED MACS THAT WILL GIVE UP TO 100x MORE REVENUE TO THE OWNER!


This is just a beginning (today one layer, tomorrow full models) but the door is already wide open. Ultra-cheap on-device training is here.

Era of Zero-Human Company isn't coming, it's already working on your Mac.

GitHub

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2069 165
Build agents that never forget anything.

(100% open-source, self-evolving memory for AI)

Most agents don't have normal memory. Every dialogue starts from scratch: without "yesterday", without understanding how facts are connected to each other.

Where they usually mess up trying to fix this?
they completely rely on vector databases and settle for that.

Vector search is fast, but it cuts documents into isolated pieces and doesn't understand how they're connected. But an agent actually needs memory that preserves connections and lives in time.

Cognee is an open-source tool exactly for this:

It combines vector search and graph databases so that documents can be searched by meaning and relationships are preserved.

What makes this even more interesting:

> Composable pipelines: assemble custom workflows by hooking in modular tasks like chunking, embeddings, and entity extraction

> Weighted memory: frequently used connections become stronger. Feedback from responses flows back into edge weights, and the graph learns what's really important

> Self-improvement: the memify pipeline uses RL-like optimization, reinforces useful paths, prunes outdated nodes, and auto-tunes based on actual usage


Getting started with Cognee looks as simple as possible:

await cognee.add("Your document here")
await cognee.cognify()
await cognee.memify()
await cognee.search("Your query")

That's it. Cognee takes on all the heavy lifting, and the agent gets memory that actually learns over time.

GitHub
••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2068 195
A big moment for text-to-speech.

Qwen has released an open source TTS model that can clone voices, create new ones, and control speech through natural language.

You can just ask
Speak in a cheerful tone with a hint of nervousness

and it will actually do it.

And without all this complex audio engineering.

GitHub

••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2067 204
arXiv Paper Curator will teach you how to build a production-ready RAG system, based on industry best practices.

GitHub

••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2066 218
Imagine you've trained your deep learning model. It works. But do you know What it actually learned?

SymTorch: a library that translates deep learning models into human-readable equations.

Attached a short video showing how SymTorch works.

I have a background in physics, and when I think about understanding a system, I think about EQUATIONS.
Equations are great: they precisely show how inputs map to outputs, which variables are important, and how the system behaves in OOD situations. Let's apply this to model interpretability.

The main principle of SymTorch is simple. For any arbitrary component of the neural network in your large architecture, we record the input and output activations on some data examples and use symbolic regression with PySR to find an equation that approximately describes the behavior of this component.

All the engineering overhead (GPU/CPU data transfer, native PyTorch model serialization, I/O caching, etc.) is already handled by SymTorch.

We've demonstrated SymTorch on a wide range of cases and architectures: from solving PDEs with PINN to understanding LLM outputs.


Paper, Website, GitHub

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2064 214
📁 Andrew Ng, one of the pioneers of AI and the co-founder of Google Brain, says that most high-dimensional data is simpler than it seems.

A dataset of dimension 10,000 often lies in a much smaller subspace.

If you first compress it, the training becomes faster, cheaper, and more efficient.

Sometimes intelligence isn't about adding more. It's about intelligently reducing.

YouTube

••••••••••••••••••••••••••••••••••••••••••
🦾 Applied AI | @PromptXplore
Post #2063 225
A madman rebuilds AlphaFold2 from scratch in pure PyTorch.

No frameworks on top of PyTorch.
No copy-pasting from the DeepMind repository.
Only nn.Linear, einsum and a 60-page supplementary from the paper.

The project is called minAlphaFold2, inspired by Karpathy and his minGPT.

🟢 What was the idea ?

AlphaFold2 is one of the most important neural networks ever built, and there should be a version that a single person can calmly sit down and read in its entirety in one day.

Current status

~3,500 lines of code in 9 modules
The full forward pass works: input embedding → Evoformer → Structure Module → all-atom 3D coordinates
All loss functions from the paper (FAPE, torsion angles, pLDDT, distogram, structural violations)
Recycling, templates, extra MSA stack, ensemble averaging — all implemented
Passes 50 tests
Each module corresponds to the numbered algorithm from the supplement to AF2

The Structure Module was the most enjoyable to put together. Invariant Point Attention is a beautiful thing: it performs attention in 3D space using local reference frames, so everything turns out to be SE(3)-equivariant, and all the math fits into about 150 lines of PyTorch.

What's next:

- Build a data pipeline (PDB structures + MSA features)
- Write a training loop
- Train on a small set of proteins and see what happen.


Repository is public. If you've ever wanted to understand how AlphaFold2 really works at the level of individual tensor operations, then this is for you.

GitHub

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2062 203
Fourier series visualization

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →