TGViewer
Channel Public Channel
Data eXplore : Data Science, ML, Big Data, LLMs and AI Security

Data eXplore : Data Science, ML, Big Data, LLMs and AI Security

@dataxplore

Exploring Data Science, Big Data Analytics & Visualization, ML/DL, Neural Networks, LLMs with GitHub, Kaggle, HuggingFace and some white papers by big institutions.

Not just data, but science behind data

Paid project? premodi@zohomail.in
★ @DataML
Subscribers
583
Photos
845
Videos
446
Links
675

Showing posts older than #2040 · Back to latest

Older Posts 20 shown
Post #2039 402
To help students better understand how analytical confidence intervals work, the guy created an interactive dashboard in Python with matplotlib.

You can adjust the sample size (n), the sample mean (x̄), the sample standard deviation (s), and the significance level (α), and immediately see the formula update in real time, along with the uncertainty distribution and corresponding confidence intervals.

Paper, Code, Model

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2038 185
DeepMind seems to have solved the "infinite memory" problem.

Published a paper on Recursive Language Models (RLM), and this essentially solves the "context decay" problem that plagues even the most powerful models like GPT-5.

🟢 How DeepMind solved the problem?
Instead of trying to "hold in memory" 10 million tokens in a single attention window, RLM treats the prompt as an external variable in a Python REPL. The model doesn't read the entire text; it "navigates" through it.

HOW IT WORKS?

The model writes code to perform grep, slice fragments, and recursively call sub-instances of itself on relevant pieces of data.

Ideal memory: When the context is externalized, the model maintains 100% accuracy regardless of document length.

EMERGENT BEHAVIOR: Without special training, the models started using regex to filter data and build recursive "check and correct" loops.

CHEAPER and FASTER: Since it only "reads" the small fragments that are actually needed, the median cost is often lower than that of regular calls with large context.

RESULTS (on Multi-Doc Research):

→ GPT-5 Base: 0% (crashed/failed)
→ GPT-5 + RLM: 91%
→ Reasoning on dense data:
→ Base: 0.04%
→ RLM: 58%


This is a complete shift from "making windows bigger" to "making navigation smarter".

Paper

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2037 170
Compressed 1.8B model to 2 bits: 600 MB in size and Dual-CoT on board.

Tencent Hunyuan has released an open-source solution for those who want to run LLMs locally on a coffee machine.

🟢 How it actually done?

HY-1.8B-2Bit - a model that has been compressed so tightly that it takes up less space than many modern mobile applications.

The model was trained using Quantization-Aware Training, which, unlike PTQ, allows adaptation to low-precision weights even at the training stage.

They took the backbone Hunyuan-1.8B-Instruct and tightly compressed the weights to 2 bits. At the same time, the effective size in memory turned out to be equivalent to a model with 300M parameters, and the physical size was only 600 MB.

Most importantly, they preserved the Dual-CoT feature: the model can switch between quick thinking for simple tasks and deep long-CoT for complex ones.

⁠➜ BENCHMARKS

⁠☞ Compared to the fp16 teacher (1.8B), the degradation of metrics is only ~4%. This is very little for 2-bit quantization.

⁠☞ Difference in accuracy compared to INT4 is negligible - 0.13%, although the model weighs 2 times less.

⁠☞ If you take a dense model with 0.5B parameters, then HY-1.8B-2Bit outperforms it on average by 16-17%. On GSM8K, the gap is even wilder: +22.29%.

⁠☞ Prefill has accelerated by 3-8 times, and token generation by 2-3 times on supported hardware.

⁠➜ A CRUCIAL NUANCE

The current implementation requires support for Arm SME2 instructions. This means that all this beauty will only work on Apple M4 and MediaTek Dimensity 9500.

If you have M1/M2 or previous-generation Snapdragon - it's not for you yet. The developers promise to add the Neon kernel later.


By the way, GGUF is also available, so if you have an M4 - you can test it. The rest have to wait for optimization for old instructions.

Model, GGUF, Technical report, GitHub | #AI #ML #SLM #2bitQ #Tencent

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2036 188
The foundation of data science.

Bayes' theorem
→ Spam filters. Medical diagnostics. Any case where you update the probability after receiving new data.

OLS loss function (sum of squared errors)
→ Linear regression. Housing price forecasting. We minimize "how much we've missed the mark".

Entropy
→ Decision trees. Information gain. A measure of how "mixed up" the classes/data are.

Normal distribution
→ A/B tests. Confidence intervals. The assumption that most values cluster around the mean.

F1-score
→ Unbalanced datasets. Fraud/scams. When accuracy misleads and gives a false sense of quality.

Sigmoid
→ Logistic regression. Neural network outputs. It converts any number into a probability.


Know the formula. Know when to apply it.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2035 202
A high-performance open-source Graph-RAG framework in Rust

EdgeQuake converts documents into "smart" knowledge graphs for better search and generation.

🟢 How it Actually works?
Classic RAG systems search for relevant text pieces mainly by vector similarity. This works fine for simple queries, but starts to falter with multi-hop reasoning (how is X related to Y via Z?), thematic questions (what are the main topics?), and connection queries. The problem is that vectors capture semantics well, but lose the structure of relationships between concepts.

EdgeQuake solves this by implementing the LightRAG algorithm in Rust: documents are not just chunked and embedded, but decomposed into a knowledge graph of entities and relationships. At the query stage, the system traverses both the vector space and the graph structure, combining the speed of vector search with the "logic" of graph traversal.

Features:

☞ ⁠Knowledge Graphs: extracting entities and building relationships with LLMs provides a structural understanding of documents, not just keyword matching
☞ ⁠6 query modes: from fast naive vector search to hybrid queries with graph traversal, for different types of questions
☞ ⁠Rust performance: async-first architecture on Tokio and zero-copy operations, handling thousands of concurrent requests
☞ ⁠Advanced PDF processing (planned, coming soon) ⚠️: table detection, multi-column layout, OCR with quality feedback mode
☞ ⁠Production ready: OpenAPI 3.0 REST API, SSE streaming, health checks, multi-tenant workspace isolation
☞ ⁠Modern frontend: React 19 + interactive graph visualizations on Sigma.js

GitHub
••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2034 199
Vector search isn't always the answer.

An algorithm from the 90s, without training, without embeddings and fine-tuning, still forms the basis of Elasticsearch, OpenSearch and most modern search engines. It's called BM25 and worth understanding why it's still going strong.

Let's say you're searching for "transformer attention mechanism" in a library of ML articles.

🟢 BM25 assesses document relevance based on three core ideas:

1️⃣ Rare words matter more than common ones

Every article contains "the" and "is", so such words carry little weight.

But "transformer" is specific and informative, so BM25 gives it significantly more weight. This is reflected in the formula through IDF(qᵢ).

2️⃣ Repetitions help, but with diminishing returns

If "attention" appears 10 times in an article, it's a strong signal of relevance. But increasing it from 10 to 100 mentions barely changes the final score.

BM25 uses saturation, controlled by f(qᵢ, D) and the parameter k₁, to prevent keyword stuffing from artificially boosting rankings.

3️⃣ Document length is normalized

A50-page article will naturally have more keyword occurrences than a 5-page one.

BM25 accounts for this through |D|/avgdl, controlled by the parameter b, to ensure long documents don't dominate the results just because they have more text.

Three ideas.
Zero neural networks.
Zero datasets.

Just meticulous mathematics that's stood the test of time.

➡️ WHAT MANY OVERLOOK?
BM25 excels at exact keyword matches, while embeddings can struggle with this.

When a user searches for "error code 5012", vector search might return semantically similar error codes. BM25 almost always prioritizes the exact match at the top.

That's why hybrid search has become the default in top-tier RAG systems.

The combination of BM25 + vector search delivers both semantics and exact keyword matches in a single pipeline.

So before throwing a GPU at any search task, consider: maybe BM25 already solves it. And if not, it'll almost certainly improve your semantic search significantly in tandem.


This hybrid search stack I mentioned above is actually already implemented in the open-source layer of the contextual retriever for agents.

GitHub

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2033 179
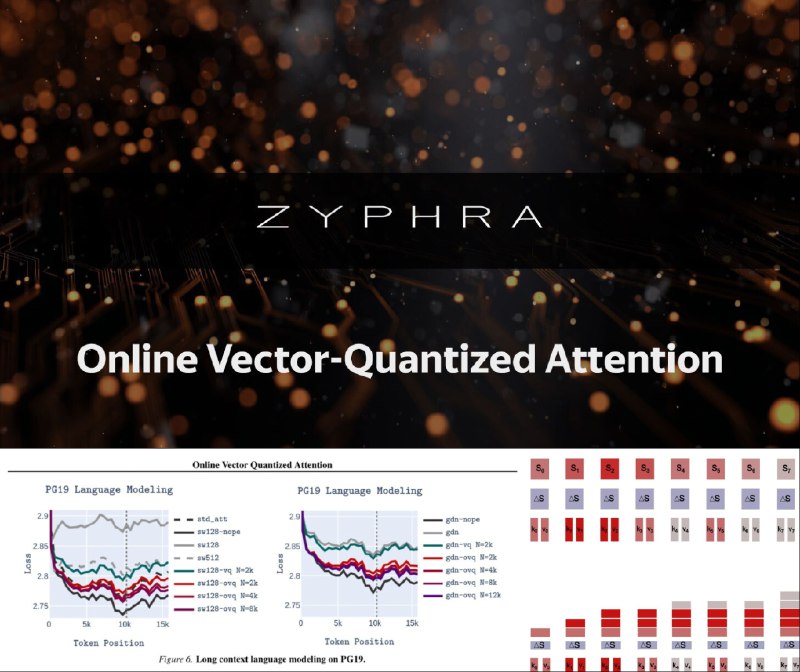
OVQA: goodbye, KV-cache offloading.

Zyphra came up with a way to sit on two chairs at once when you want rubbery context but don't have a ton of memory on hand.

What they proposed is called Online Vector-Quantized Attention - it's a modification of vector quantization that teaches the dictionary to think on the fly.

🟢 What they done?

In classic VQ, keys are replaced by the nearest centroids from a static dictionary. This boosts computations but creates a problem: the dictionary is trained on one set of data, but during generation, the model sees a completely different distribution of keys. The quantization error grows, attention loses accuracy, and as a result: VQ starts to falter.

So, the modification is to abandon the static dictionary in favor of one adapted to the current sequence: each new token updates only one centroid - the one it's closest to.

This sparse update works as a protection against catastrophic forgetting: old information isn't washed away by a new wave of tokens, but is carefully overwritten as needed.

There's also a hard limit on the state size, after which the amount of memory stops growing and computations become strictly linear.

➜ Results of test experiments

☞ A model trained on 4K tokens confidently handled context up to 64K without quality degradation;

☞ On in-context search, OVQ almost kept up with full self-attention while consuming 4 times less memory;

☞ On In-Context Learning, VQ failed, but OVQ reached the level of classic attention using only ~4K centroids;

☞ Comparisons with linear alternatives (Mamba2 and delta networks) also favor OVQ: it more stably holds long context without accuracy drops;

➜ In Positional ICR tasks, OVQA performs slightly worse than classic attention but still decently.

We really hope that OVQ is the precursor of true continuous learning, where in the bright future, instead of an infinitely swelling KV-cache, there will be compact but living memory capable of holding important details without losses.


Article, PDF • #AI #ML #LLM #OVQA #Zyphra

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2032 165
Do you need to find the greatest common divisor of two numbers?

Just add them together until you can't add anymore.

This works because the greatest common divisor of a and b is equal to the greatest common divisor of a and b - a.

And "adding" one number line to another is essentially calculating the difference.

The second animation starts with 34 and 55.

These are two neighboring Fibonacci numbers, and the process descends through the entire Fibonacci sequence to 1. A beautiful proof that neighboring Fibonacci numbers are mutually prime.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2031 173
HY3D-Bench: 22 terabytes of selected 3D geometry.

Tencent Hunyuan released a monstrous HY3D-Bench dataset of 22.5 TB to the open-source community, which is a gift for everyone involved in 3D Gen and robotics.

🟢 What is inside?
The dataset is divided into three logical parts, each for specific tasks:

☞ Full-level Dataset (252K+ meshes, ~11 TB)
A database with fully closed geometry, without holes or non-manifold artifacts that typically plague scans. Everything is normalized and ready to be fed into DiT or GAN. It includes point samples and multi-view renders.

☞ Part-level Dataset (240K+ objects, ~5 TB)
A treat for robotics enthusiasts and those working on geometric perception. It contains objects with semantic segmentation into parts. If you're teaching a servo-driven friend to manipulate objects or want to generate objects piece by piece - this is for you.

☞ Synthetic Dataset (125K+ objects, ~6.5 TB)
Obvious synthetics to cover rare categories not found in regular datasets. It covers 1252 categories.

Waiting for a wave of SOAT-level 3D generators tuned on this dataset.

Paper, Dataset, GitHub | #AI #ML #Dataset #HY3DBench #Tencent

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2030 315
Graph-based RAG with dual-level retrieval.

LightRAG is an open-source RAG framework that builds knowledge graphs from documents and uses dual-level retrieval to answer both point-based and conceptual queries.

🟢 Why it matters?

Classical RAG relies on vector similarity and flat chunks. This is enough for superficial queries, but it breaks down when you need to understand how different concepts are connected.

LightRAG solves this problem by extracting entities and their relationships and forming a structured knowledge graph.

It uses LLMs to find entities (people, places, events) and their relationships in documents, then assembles a full-fledged knowledge graph that preserves these connections.

The framework works with dual-level retrieval:

Low-level retrieval targets specific entities and details, for example: What is Mechazilla?

High-level retrieval aggregates information across multiple entities for more general questions
such as: How does Elon Musk's vision contribute to sustainable development?

For each query, LightRAG extracts local and global keywords, matches them to graph nodes via vector similarity, and pulls in neighboring nodes one step at a time to expand the context.

What sets it apart:

• Graph-based indexing preserves connections between concepts rather than turning knowledge into isolated pieces
• Dual-level retrieval works for both point-based and conceptual queries
• Automatic entity extraction without manual labeling
• Incremental updates — new data is added without completely rebuilding the graph
• Multimodal support via RAG-Anything for PDFs, office documents, images, tables, and formulas

Key features:

✅ Knowledge graph visualization via WebUI
✅ Multiple storage backends (PostgreSQL, Neo4j, MongoDB, Qdrant)
✅ Support for major LLM providers (OpenAI, Anthropic, Ollama, Azure)
✅ Support for rerankers for mixed queries
✅ Document deletion with automatic knowledge graph regeneration


100% open source.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2029 327
Someone has collected a collection of all production-ready LLM applications that can be made in 2026.

It's called awesome-llm-apps. It's literally copy-paste code for RAG, agents, multimodal applications, and AI SaaS products.

→ Need RAG? Copy the code.
→ Need AI agents? Copy the code.
→ Need multimodal applications? Copy the code.

No hello world.
No training demos for beginners.
Only real applications that can be deployed today.


100% free. 100% Open Source.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2028 172
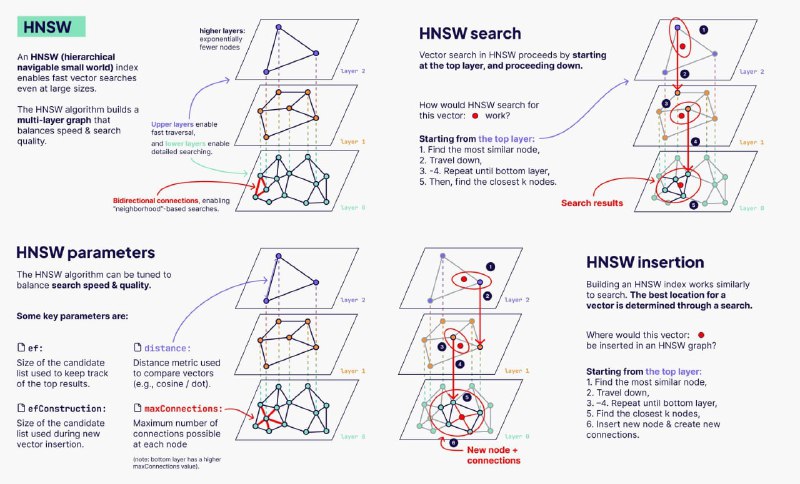
Hierarchical Navigable Small World (HNSW) is an algorithm that makes vector search fast even on huge amounts of data, allowing you to search billions of vectors in milliseconds.

The idea of its operation is quite elegant - it's one of the most interesting discoveries of recent years.

🟢 How it works?
HNSW builds a multi-level graph, where each upper layer contains exponentially fewer nodes than the layer below.

☞ All vectors are located in the lower layer (layer 0), which is well connected.
☞ Only some vectors appear in layer 1, even fewer in layer 2, etc.
☞ The upper layers work as "fast lanes", allowing you to skip a large number of irrelevant data.

During the search, the algorithm starts from the upper layer, finds the nearest node, descends to the lower layer and repeats the process. By the time you reach the lower layer, you have already narrowed the search to the most relevant environment - there's no need to sort through everything.

This explains why HNSW is so economical with memory. It can "jump over" large amounts of data without evaluating each element.

Key parameters that affect the balance of speed and quality:

☞ ef - the size of the candidate list during the search
☞ maxConnections - how many connections each node can have
☞ distance - a metric for comparing vectors (cosine, dot product, etc.)

Adding new elements works in a similar way: first, we search for the optimal location, then we create connections. Restructuring the graph is resource-intensive, but queries themselves are performed very quickly.


You can read more in detail here ✅

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2027 163
KMeans clustering animation in the style of 3blue1brown


•••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2026 209
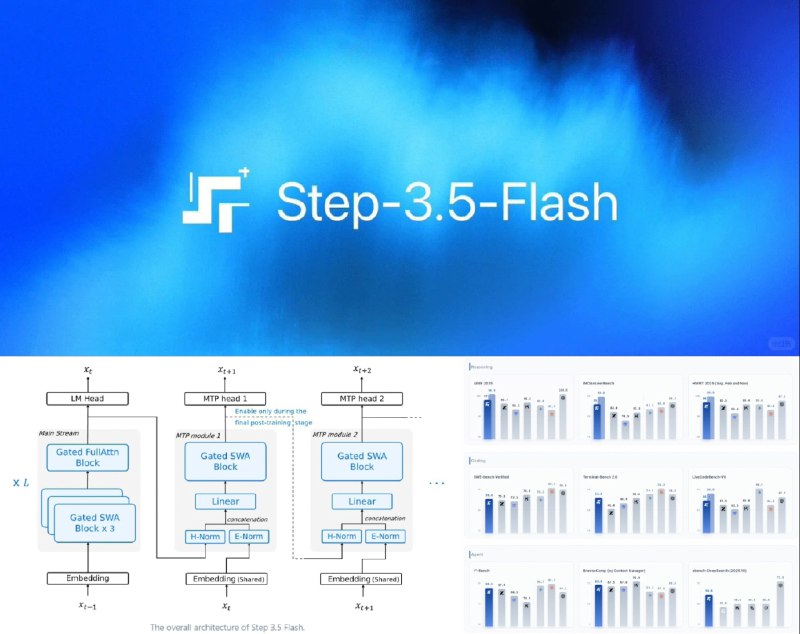
Step 3.5 Flash: a model with a hybrid attention architecture and a speed of up to 350 T/s.

a very interesting MoE model with 196 billion total and 11 active parameters.

Authors claim an insane speed of up to 300 tokens per second, and on tasks with code, it supposedly accelerates to 350. For a model of this level, this is very impressive.

🟢 What's going on inside?

Instead of the standard attention mechanism, they used a hybrid scheme: one layer of full attention on 3 sliding window layers, which allowed them to cram a context of 256 thousand tokens into the model without clogging up the memory to the point of failure.

In training, they used the MIS-PO algorithm, which helped solve the problem of losing the thread in long CoTs and simply cuts off options that deviate too much from logic.

The model, as is now fashionable, was tailored for autonomous agents. It can use ten tools at the same time. In Deep Research mode, the model itself googles, plans stages, and writes reports up to 10 thousand words long.

If you need to run a heavy code repository through the model, it handles it without the usual slowdowns that occur when working with voluminous texts.

⁠➜ BENCHMARKS

Step 3.5 Flash scored 97.3 on the AIME 2025 test (and this is bare risoning, without third-party calculators). If you give it access to Python, the result soars to 99.8.

On code benchmarks, the numbers also look impressive: on SWE-bench, it gives 74.4%, and on Terminal-Bench 2.0 - 51.0%.

Of course, in terms of knowledge density, Step 3.5 Flash still lags behind Gemini 3.0 Pro, but the fact that it is available for local use and tests via API, is pleasing.


Article, Model, Demo, Discord Community, GitHub • #AI #ML #LLM #StepFunAI

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2025 169
Dude completely implemented the architecture of GPT-OSS-20B from scratch in PyTorch. All components were written from scratch:

⁠☞ RoPE with YaRN + NTK-by-parts for context scaling
⁠☞ RMSNorm
⁠☞ SwiGLU with clamping and residual connections
⁠☞ Mixture-of-Experts (MoE)
⁠☞ Self-Attention, optimized via Grouped Query Attention (GQA)
⁠☞ Learned sinks
⁠☞ Banded (sliding window) attention
⁠☞ Support for KV caching

All of this works on a single A100 SXM (80GB). He also wrote detailed documentation with the theory of each component, as well as instructions for setup and inference.

Repository

••••••••••••••••••••••••••••••••••••••
🤖 Data & ML |
@DataXplore
Post #2024 189
ACE-Step v1.5: Ace Studio in collaboration with StepFun have updated the ACE-Step, local music generator to version 1.5.

The entry threshold has been lowered to a minimum: the junior model requires less than 6 GB of video memory, and, depending on the think mode settings, generation can take from 2 to 10 seconds - this is already the level of commercial solutions.

🟢 What they did?

The developers have assembled a hybrid of a language model that turns a prompt into a composition sketch: it outlines the structure, comes up with lyrics and metadata, and DiT, which is responsible for the sound. The logical core of this entire system is based on Qwen3.

ACE-Step v1.5 can generate tracks from 10 seconds to 10 minutes long, with up to 8 tracks at a time. There are more than 1000 instruments in the database, and the system understands lyrics in 50 languages.

The authors have prepared a whole set of models for different amounts of VRAM:

⁠➜ Less than 6 GB: without the LM module, only the sound engine works.

⁠➜ 6-12 GB: a lightweight version of LM (0.6B).

⁠➜ 16 GB and above: a full-fledged model with 4 billion parameters, which best understands the context and delivers maximum quality
.
When launched, ACE-Step v1.5 automatically selects a model and parameters suitable for the hardware. Detailed information on configurations can be found here.

ACE-Step can do much more than just turn text into a melody. You can give it an audio example to copy the style, make covers, correct parts of already finished tracks, or generate an accompaniment for vocals.

The most interesting feature is the ability to create LoRA. To feed the model with your own style, just 8 tracks are enough. On the 30th series RTX with 12 GB of memory, this process will take about an hour.

Everything is in order with the deployment, the developers have prepared a portable build, and for ComfyUI they have already written all the necessary nodes and workflows.

Project page, Model, Paper, Demo, Discord community, GitHub • #AI #ML #Text2Music #AceStudio #StepFun

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2023 380
Data eXplore : Data Science, ML, Big Data, LLMs and AI Security HOW YOLO BECAME A STANDARD IN CV? Launching a series of posts about the evolution of one of the most popular architectures in computer vision. We'll break down: Before 2015, the task of detection was solved by searching for the most likely regions. There…
Continue the series of posts on evolution of most popular model family for Object Detection.

Development ceased to be purely conceptual and became more engineering-oriented:

🟢 Review of YOLO v4-v6
➡️ YOLO v4: Model turned into an engineering encyclopedia (2020)

YOLO v4 became a "BIBLE" for improving architectures. It packed in as many tricks as possible without killing FPS.

GOLDEN FEATURE: In new version, mosaic augmentation was introduced. It collects training picture from several different ones, which improves model's performance. As a result, the quality was improved by +6% mAP compared to YOLOv3, while maintaining a speed of 60 FPS.

OTHER CHANGES: Pyramidal architecture (CSPDarknet-53 + PANet + SPP). Instead of simply cutting out pieces from picture, a multi-scale approach was implemented at level of network itself. Network itself extracted features of different scales and recognized contexts.

TRICKS & AUGMENTATIONS. Architecture integrated such developments as Mish-activation, DropBlock, and CloU loss. Together with mosaic augmentation, they improved model's quality by 10% without drastically changing it.

DOWNSIDES of YOLO v4 include difficulty of integrating model and manual hyperparameters left over from previous versions.

There are no more problems to fix, so developers focused on improvements.

➡️ YOLO v5: "Ugly Duckling" and mass adoption (2020-2021)

YOLO v5 was released four months after v4 - version was nicknamed "Ugly Duckling", because there were no architectural breakthroughs in it.

GOLDEN FEATURE: YOLO v5 was rewritten in PyTorch and made it more user-friendly. Everyone could integrate it into their project and retrain it for their own tasks. PyTorch soon gained popularity and dominated the DL field, which led to mass adoption of YOLO.

There weren't many other features - they were released to promote article about the new version. But there were a lot of problems:

📎 Version didn't work due to bugs. For first two months, the buggy implementation simply didn't allow to use model. Memory leaks, incorrectly specified areas for three candidates.

📎 Version didn't add anything new. Each new YOLO either solved an engineering problem or an idea problem. Fifth model was considered a rewrite of what already existed - just on a different framework. Community didn't like this approach.

📎 Version was developed by Ultralytics. Community was wary of it: previously, YOLO was developed by a CIS superstar in the CV field - Bachkovsky and now it's some no-names. So developers were worried about fate of beloved model.

📎 Version never got an article. Company promised to release it within a few months. But it's been four years - Article hasn't appeared. They just released a couple of technical reports on archive.

Fortunately, Ultralytics didn't abandon model and kept improving and enhancing it. Thanks to PyTorch and support from developers, YOLO v5 is widely used as a component of a comprehensive solution.

➡️ YOLO v6: Model was made more convenient for deployment (2022)

Company focused on developing most convenient real-time deployment for frameworks like TensorRT and Edge devices.

GOLDEN FEATURE: An Anchor-Free Head was introduced. Instead of predicting shifts for candidates, Model searches for exact center of object. It's faster and more accurate.

OTHER INNOVATIONS: New architecture. EfficientRep, an analogue of EfficientNet, was chosen as the backbone. They also abandoned DarkNet backbone - it was outdated.

HIGH SPEED. Model became super-lightweight and demonstrated 120 FPS on a T4 at a resolution of 640x640. Therefore, it was used in tasks related to thermal imagers and Edge computing.

There were no obvious downsides or problems with the model. Except for the accuracy compared to v5 and v7. But v6 is best for Edge devices.


In next post, we'll discuss at Why YOLO v8 became the most popular model in the family? and
How commercialization turned the project into a conveyor?

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML |
@DataXplore
Post #2022 183
Every second tutorial on RAG is either a toy or a research project disguised as a product.

That's not true. Agentic RAG, made properly:

→ hierarchical search (first child elements, parent - on request)
→ dialogue memory
→ refinement of requests
→ parallel agents


GitHub

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2021 186
Guardrails is no longer a "last thought" or a bonus to the project - these are key architectural patterns that determine whether you can safely deploy your agent system.

Below are four working patterns we have seen in production systems:

1️⃣ Adaptive feedback loops
Agents perform tasks → Supervisor evaluates → Reward service updates policies → Guidelines are adjusted → Agents improve over time.
A continuous learning cycle is created, where the system reinforces effective behavior and reduces risky behavior. This is reward-based learning, which improves with each iteration.

2️⃣ Corrective action
A centralized Supervisor distributes tasks, compares results with the application's guidelines, and connects alternative agents if errors are detected. The best verified result is returned to the user. This prevents a bad result from reaching end users.

3️⃣ Human in the loop
For sensitive domains (medicine, law, finance), agents generate preliminary responses, but a human validates them before execution. The flow is automatically paused for expert review and resumes only after approval.

4️⃣ Emergency stop
Critical for high-risk systems, such as trading.
Agent 1 collects market data → LLM processes signals → Agent 2 evaluates conditions → if anomalies or risks are detected, execution is immediately stopped.
Example: a trading bot with access to a volatility API showing VIX = 42 (extreme market stress). Even if the bot suggests an aggressive trade, the evaluator independently checks: "Is this adequate given the current volatility?" If not - the action is completely blocked.

The underlying philosophy is behavior shaping: a three-step loop of evaluation → feedback → correction. The evaluator doesn't just record the result post-factum. He actively intervenes: rolls back bad transactions, stops flows with incorrect data, or redirects complex cases for human verification.

It's especially important when agents interact with unstable external states - market conditions, API health, system load. The evaluator provides a sanity-check to ensure that the model correctly interpreted the signals and didn't just generate coherent text.


The goal is not to catch all errors in advance (this is impossible). The goal is to build systems that detect problems on the fly, understand what went wrong, and automatically correct the course before the damage spreads.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Post #2020 165
It's possible to build an LLM from scratch.

There's a repository that breaks down the complex mathematics of Transformers into understandable, clean Python. It covers the entire lifecycle of an LLM.

→ step-by-step implementation
→ simple, "hackable" examples

100% open source.

••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →