TGViewer
Channel Public Channel
Data eXplore : Data Science, ML, Big Data, LLMs and AI Security

Data eXplore : Data Science, ML, Big Data, LLMs and AI Security

@dataxplore

Exploring Data Science, Big Data Analytics & Visualization, ML/DL, Neural Networks, LLMs with GitHub, Kaggle, HuggingFace and some white papers by big institutions.

Not just data, but science behind data

Paid project? premodi@zohomail.in
★ @DataML
Subscribers
584
Photos
845
Videos
446
Links
675

Showing posts older than #1763 · Back to latest

Older Posts 20 shown
Post #1762 162
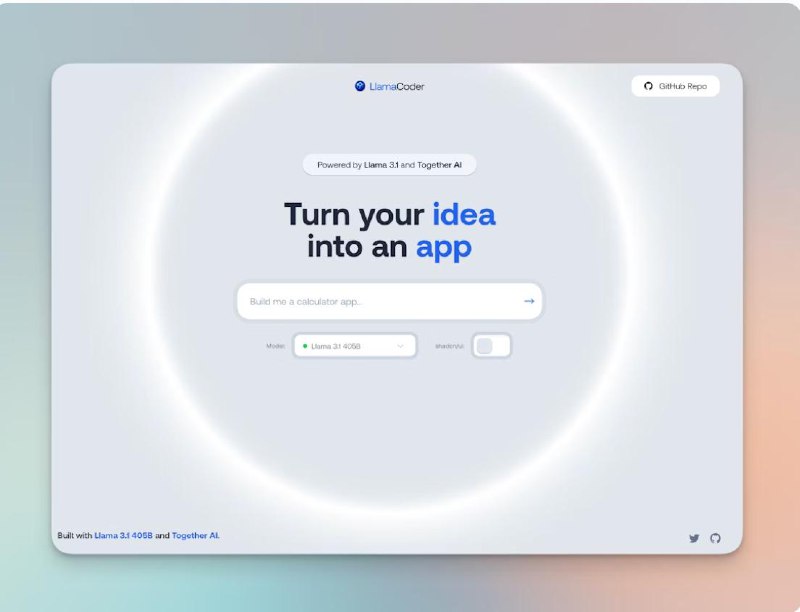
How to build a "Lovable Clone" with the Kimi K2 model?

The TogetherAI explains how to create an application in Next.js that generates a ready React app from a text prompt, literally "Code From A Single Phrase."

🟢 The checklist describes the main steps…
- Create a simple UI with a query input field (*“Build me a calculator app…”*).
- Implement the API route /api/generateCode that sends a request to the Kimi K2 model via the Together AI SDK.
- Use a system prompt so the model returns only code, without comments.
- Embed Sandpack or a similar tool to run the code directly in the browser.
- Add streaming so the user can see the code appear in real time.


Find Here

🤖 Data Science, ML & Big Data with @DataXplore
Post #1759 168
Google published a 150-page report on Health AI Agents - 7,000 annotations, 1,100+ hours of expert work.

But the main point is not the metrics, but the new design philosophy.

🟢 How it's actually different than monolithic *"Doctor-GPT"*?

Google is creating a Personal Health Agent (PHA) - a system of three specialized agents:
- Data Science Agent - analyzes wearable devices and lab data
- Domain Expert Agent - verifies medical facts and knowledge
- Health Coach Agent - conducts dialogue, sets goals, adds empathy

🧩 Everything is connected by an orchestrator with memory: user goals, barriers, insights.

⚡ Results
- Outperformed baseline models on 10 benchmarks
- Users preferred PHA over regular LLMs (20 participants, 50 personas)
- Experts rated answers 5.7–39% better on complex medical queries

⚙️ Design principles
- Consider all user needs
- Adaptively combine agents
- Do not ask for data that can be inferred
- Minimize latency and complexity

🧠 Tested scenarios
- General health questions
- Data interpretation (wearables, biomarkers)
- Advice on sleep, nutrition, activity
- Symptom assessment (without diagnosis)

⚠️ Limitations and future
- Slower than single agents (244 s vs. 36 s)
- Need bias audits, data protection, and regulatory compliance
- Next step - adaptive communication style: empathy ↔ responsibility


Google shows the way forward: not a "super doctor bot", but modular, specialized agent teams.
Medicine is just the first test. Next: finance, law, education, science.

Google 150 Health AI Agents

🤖 Data Science, ML & Big Data with @DataXplore
Post #1758 532
💡 Google has launched Skills: an open platform for developing AI skills!

🟢 What you will get here?
The platform features nearly 3000 courses, labs, and practical tracks covering topics from Python basics and machine learning to advanced MLOps, Vertex AI, Gemini, and Prompt Design.

You can learn…
… Integrate generative AI into your data pipeline;
… Learn how to deploy and maintain models;
… Create your own app with Gemini and Streamlit;
… Get training with mentors or in the Google Cloud Innovators community.


Various levels from beginners to team leads. Upon completion, you even receive certificates that you can add to your resume and LinkedIn.

Start learning and check-out catalog

#Google #AI #FREEcourse

🤖 Data Science, ML & Big Data with @DataXplore
Post #1757 146
Google Gemini has been taught to recognize exploding stars from 15 examples

Now Gemini can detect *supernova flashes and other astronomical events* literally from just a few training examples.

🟢 Why this matters?
- Future telescopes like the Vera Rubin Observatory will generate *millions of signals every night* — impossible to process without AI
- The few-shot approach allows quick adaptation of the model to new data without retraining
- Gemini becomes a scientific assistant, not just a classifier

☞ The Main points
- Used few-shot learning — only about 15 examples for each observatory *(Pan-STARRS, MeerLICHT, ATLAS)*
- The model sees three images: new, reference, and the difference between them
- Gemini not only labels but explains *why* it considers the event genuine
- Average accuracy — 93%, after iterations up to 96.7%
- Can assess its own uncertainty and ask for human help
- Model explanations were recognized as reliable by expert astronomers


🔴 Limitations
- 93% ≠ 100% — a human-in-the-loop is still necessary
- The model is sensitive to the quality of examples and can err on rare artifacts


Gemini now not only analyzes images but *learns to think like a scientist* : explaining, doubting, and adapting to new tasks.

🤖 Data Science, ML & Big Data with @DataXplore
Post #1756 487
NVIDIA OmniVinci

An omnimodal model that capable of simultaneously understanding and processing different types of information: text, images, video, and sound.

🟢 How did NVIDIA make a model this efficient?
The model is extremely efficient despite being trained on only 200 billion tokens (which is 6 times less than Qwen2.5-Omni - 1.2 trillion). This was made possible thanks to architectural features and a careful approach to data preparation.

OmniVinci is based on 3 components:

☞ Temporal Embedding Grouping (TEG) - organizes embeddings from video and audio by timestamps.

☞ Constrained Rotary Time Embedding (CRTE) - encodes absolute time.

☞ OmniAlignNet - aligns video and audio embeddings in a common latent space using contrastive learning.

Ablation showed that each element plays its important role: the base model with simple token concatenation scores an average of 45.51 points. Adding TEG raises the result to 47.72 (+2.21), CRTE — to 50.25 (+4.74 from the base), and the final layer in the form of OmniAlignNet brings the average score to 52.59, which in total gives an increase of 7.08 points.

Training data consisted of 24 million dialogues, which were processed through a system where a separate LLM analyzes and combines descriptions from multiple modalities, creating a unified and accurate annotation.

The final dataset consisted of 36% images, 21% sounds, 17% speech, 15% mixed data, and 11% video.

In benchmarks, OmniVinci outperformed all competitors. On Worldsense, the model scored 48.23 points versus 45.40 for Qwen2.5-Omni. On Dailyomni - 66.50 versus 47.45. In audio tasks, OmniVinci also performed well: 58.40 in MMAR and 71.60 in MMAU.

In speech recognition, the model showed a WER of 1.7% on the LibriSpeech-clean dataset.

The model's application was tested in practice. In the task of classifying semiconductor wafer defects, OmniVinci achieved an accuracy of 98.1%, which is better than the specialized NVILA (97.6%) and the larger 40-billion-parameter VILA (90.8%).


Code licensing: Apache 2.0 License.
Licensing: NVIDIA One Way Noncommercial License.

Project page, Model, GitHub

#AI #ML #NVIDIA #OmniVinci

🤖 Data Science, ML & Big Data with @DataXplore
Post #1755 165
⚡️ BERT is just a Single Text Diffusion Step

An interesting post where the author explained that what we call text diffusion is actually just a generalized version of classic BERT training.

🟢 How does BERT work?
In BERT, the model takes text and masks some words, then learns to guess which words were hidden.
In diffusion, almost the same thing happens, but with more steps: at each step, the model slightly "damages" the text (adds noise), then restores it, losing less and less meaning until it collects the final clean text.

So BERT performs one denoising step, “GUESSING THE MASKED WORDS.”

And the diffusion model performs many such steps in a row, gradually turning a random set of tokens into meaningful text.

Barry fine-tuned RoBERTa to demonstrate this in practice and got a real text diffusion generator.

In the example:
- RoBERTa (an improved version of BERT) and the WikiText dataset are used.
- At each step, some tokens are replaced with <MASK>, the model restores them, then masks again — and so on several times.
- After several iterations, the model can generate coherent text, even without an autoregressive decoder (like GPT).


The author mentions that later he came across the work DiffusionBERT, where the idea was implemented more deeply and confirmed with results.

Main idea is that BERT can be considered a single-step version of text diffusion.
If you add more steps, you get a diffusion text generator.


The model generates meaningful text, although not perfectly coherent. If BERT is one diffusion step, then the future may belong to models combining "understanding" and "generation" of text in one process.

#AI #Diffusion #RoBERTa #BERT #LanguageModel #MLM #Research

🤖 Data Science, ML & Big Data with @DataXplore
Post #1754 539
Data eXplore : Data Science, ML, Big Data, LLMs and AI Security The situation in AWS right now 🤖 Data Science, ML & Big Data with @DataXplore
When your AI girlfriend lived on AWS us-east-1 💔*

Everything was great until the AMAZON data center went down.

🤖 Data Science, ML & Big Data with
@DataXplore
Post #1753 164
📄 DeepSeek-OCR

DeepSeek has released a powerful OCR model for text recognition, capable of converting document images directly into Markdown or text.

🟢 Features:
- Recognizes text in images and PDFs
- Works with documents, tables, and complex layouts
- Supports different modes: Tiny, Small, Base, Large
- Optimized for GPU (PyTorch + CUDA 11.8)
- MIT license — free to use and modify


DeepSeek-OCR achieves high accuracy and efficiency through visual token compression. On Omnidocbench, it has the best accuracy with minimal visual tokens, outperforming other OCR models in efficiency and speed.

Can find HF, Github, Paper

#OCR #DeepSeek

🤖 Data Science, ML & Big Data with @DataXplore
Post #1752 512
The situation in AWS right now

🤖 Data Science, ML & Big Data with @DataXplore
Post #1751 225
Alibaba found a way to reduce GPU demand by 82%

Most often in the cloud, where several models are hosted, each model is tied to specific GPUs. For example, Llama-70B → 8× A100.

And even if no one is currently querying the model, the GPU remains reserved and idle because the weights are already loaded.

🟢 How Aegaeon helps?
Alibaba discovered that this seemingly innocent idling actually consumes a huge amount of resources. It turned out that in their cloud 17.7% of all GPUs were occupied by models that processed only 1.35% of all requests. First, this is terribly inefficient. Second, such a system is very hard to scale if more models appear.

So they took on optimization and proposed something called Aegaeon (don’t know how to pronounce it). This is a system where instead of a one-to-one mapping of "model-to-GPU", each GPU can handle multiple models simultaneously.

It’s somewhat similar to Kubernetes: the cluster turns into a unified pooling system that can dynamically allocate and free memory.

The main idea is that the system switches at the token level, not whole requests. Usually, a model is loaded into memory entirely and runs until it finishes the response. Aegaeon breaks the process into prefill and decode, alternating them between models right during generation.

This happens without full initialization: the scheduler caches the necessary parts in VRAM and loads the rest as needed. So there are delays, but minimal – within 3-5%.

Currently, Aegaeon is already running directly in Alibaba Cloud. And engineers claim they managed to reduce the number of required GPUs from 1192 to 213. That’s a minus 82%!


Necessity is the mother of invention who were banned from importing GPUs 🍿

🤖 Data Science, ML & Big Data with @DataXplore
Post #1750 144
One of the clearest visualizations of The Attention Mechanism : a topic that many developers have long found difficult to truly understand.

At first glance, the formula seems simple, it is easy to learn and even reproduce from memory.

But intuitively understanding how Q (Query), K (Key) and V (Value) interact is a completely different matter. This diagram helps to “see” what happens inside the transformer.

#Machinelearning #Deeplearning #Transformers #Attention #LLM

🤖 Data Science, ML & Big Data with @DataXplore
Post #1749 609
Anthropic discovered a troubling vulnerability in training language models.

Just 250 planted documents are enough to "implant" a hidden command (backdoor) into a model ranging from 600 million to 13 billion parameters - even if there are 20 times more normal examples among the data.

🟢 What is the key finding?
It is not the percentage of infected documents, but their absolute number that determines the success of the attack. Increasing data volume and model scale does not protect against targeted poisoning.

The backdoor remains unnoticed - the model works as usual until it encounters the secret trigger, after which it starts executing malicious instructions or generating nonsense.

Even if training continues on "clean" data, the effect fades very slowly - the backdoor can persist for a long time.


Protecting LLMs requires controlling data provenance, verifying corpus integrity and measures to detect hidden injections.

🤖 Data Science, ML & Big Data with @DataXplore
Post #1748 412
Stack Overflow is still alive💥

Stack Overflow AI is a tool where you can ask coding questions and immediately get clear, detailed answers with explanations.

The model is trained on real questions and tasks from developers accumulated by Stack Overflow over the years of the service's existence.

You can Try Here

🤖 Data Science, ML & Big Data with @DataXplore
Post #1747 222
Who is really driving open-source AI?

Analysis of the top 50 most downloaded models on Hugging Face

🟢 Which organizations and types of models define the open model ecosystem?

The top 50 represent only 3.4% of all models on Hugging Face, but they account for more than 80% of 45 billion downloads.

The vast majority of activity is concentrated around a small group of leaders, these models shape the face of all open-source AI.

📉 Size matters (and the smaller, the better):
- 92.5% of downloads are models < 1B parameters
- 86.3% — < 500M
- 70% — < 200M
- 40% — < 100M

Clear conclusions: in open-source, small and lightweight models that are suitable for local deployment and edge inference win.

🧠 Popular directions:
- NLP — 58.1%
- Computer Vision — 21.2%
- Audio — 15.1%
- Multimodal — 3.3%
- Time Series — 1.7%

Who creates the most downloaded models?
- Companies - 63.2% (Google leads)
- Universities - 20.7%
- Individual authors - 12.1%
- NGOs - 3.8%
- Other labs - 0.3%

Which types of models win:
- Text encoders - 45% of all downloads
- Decoders - only 9.5%
- Encoder-decoders - 3%

Despite the hype around LLMs, it is not the giants but the utility models that are massively downloaded for integration into proprietary products.

The USA dominates in all categories:
- appears 18 times among the top 50 downloads
- accounts for 56.4% of all downloads


Open-source AI thrives not because of giant LLMs but thanks to compact, fast and practical models that actually work in products and projects.

#AI #HuggingFace #OpenSource #ML #Research #LLM #AITrends

🤖 Data Science, ML & Big Data with @DataXplore
Post #1746 128
Do you know How Google Optimizes Data Centers Using AI?

Remember Tetris. You need to fit the pieces as tightly as possible so there are no empty spaces. A very similar problem arises in cloud data centers like Google Cloud.

🟢 In-depth Explanation!?
There are physical servers running virtual machines for different tasks. These VMs appear, run for some time, and then disappear. Some VMs are taken for testing and run for 15-20 minutes, while others host databases for months.

You cannot know in advance how long a VM will live. At the same time, there is a specific optimization problem: to pack them in a way that uses resources as efficiently and densely as possible. Just like in Tetris.

Simple optimization does not work here precisely because of the uncertainty. So Google thought it through and attached a probabilistic ML model.

It predicts the probability distribution of a VM's lifetime based on the general distribution (which, by the way, is heavily skewed), VM metadata, user behavior, creation method, etc. The output is something like "With 80% probability this VM will live for an hour, with 15% probability – a day, and 5% – longer than a week." This is called survival analysis.

Interestingly, the forecast is dynamic and updates over time. For example, if the VM is still running after 10 days, the model revises the estimate.

And based on this predicted distribution, optimization algorithms operate. For example, a scheduler tries to place several identical VMs on one server to free it completely later. Or an algorithm places short-lived VMs on servers with long-lived ones to fill small gaps that would otherwise be lost.

And the metrics. Google has already tested this approach on their servers and (attention!) equipment downtime has decreased on average by 5%. Imagine how much that is in dollars


Great work and a cool case 🙂

🤖 Data Science, ML & Big Data with @DataXplore
Post #1745 126
ShinkaEvolve: Evolution of programs with AI

ShinkaEvolve is a framework that combines large language models with evolutionary algorithms to automate scientific discoveries. It enables improving scientific code by leveraging the creative capabilities of AI and optimization through evolution, supporting parallel evaluation of candidates.

🟢 Key points
- Combines LLM and evolutionary algorithms.
- Supports parallel evaluation on local machines and clusters.
- Stores an archive of successful solutions for knowledge transfer.
- Optimizes performance while maintaining code correctness.
- Ideal for scientific tasks with available verifiers.


GitHub

#python

🤖 Data Science, ML & Big Data with @DataXplore
Post #1744 630
Omni-Embed-Nemotron

The new unified model from NVIDIA is trained on diverse multimodal data and can combine different types of input signals into a common vector representation.

🟢 What are the Features?
- Searching supports all data types: text, image, audio, video.
- Based on the Qwen Omni architecture (Thinker module, without text generation).
- Context up to 32,768 tokens, embedding size — 2048.
- Optimized for GPU, supports FlashAttention 2.

This makes it ideal for…
- cross-modal search (searching text by video or image);
- enhancing RAG projects;
- multimodal content understanding systems.


Simple, fast, and efficient - all in one open solution.

Open model on Huggingface

#crossmodal #retrieval #openAI #NVIDIA #OmniEmbed #multimodal #AIModels #OpenSource #Search #UnifiedEmbedding

🤖 Data Science, ML & Big Data with @DataXplore
Post #1743 133
MobileLLM-Pro

This language model (~1B parameters) optimized for efficient *on-device* operation.

🟢 Why it's good?
Outperforms Gemma 3 1B and Llama 3.2 1B in reasoning, knowledge, and long context tasks, supporting up to 128,000 tokens.

Thanks to hybrid attention (local + global in a 3:1 ratio, window 512), it achieves low latency and KV-cache memory savings.

Quantization to 4-bit (int4) barely reduces quality:
• CPU - group weight quantization and dynamic activation
• GPU - per-channel quantization


The model has also undergone instruction fine-tuning, making it suitable for communication, generation, and text processing tasks.

Model

🤖 Data Science, ML & Big Data with @DataXplore
Post #1742 149
rm -rf

And I thought the Argentine was about German roots
Older posts →
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook →Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 →