
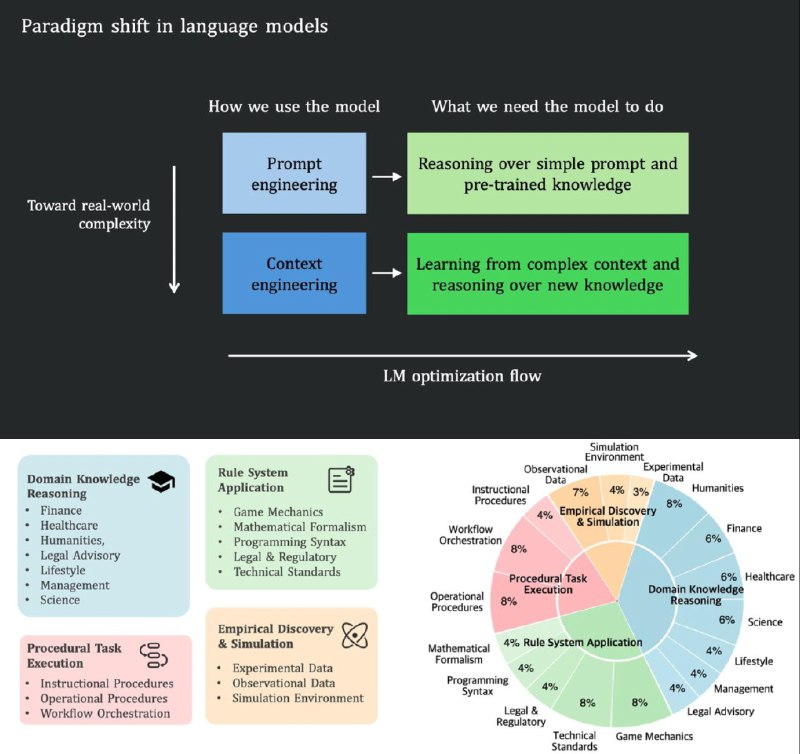
Open-source benchmark CL-bench has been released - and this isn't just another dataset, but an attempt to shift the focus of the entire industry.
🟢 What they done?
Tencent HY, in collaboration with Fudan University, have published a new work:
“CL-bench: A Benchmark for Context Learning” - a systematic benchmark for evaluating whether *models are actually able to think in context*, rather than just recalling what they've learned.
This is the first research release from Vinces Yao's team since his move to Tencent - and it's clear from their ambitions that they're aiming for fundamental changes.
Today, most LLMs operate according to the following scheme:
huge weights + memorized patterns = answers
But the real world isn't a memory test. It's about:
- long, complex contexts
- conflicting information
- the need to change strategies on the fly
- drawing conclusions based on what's just appeared
Models need to move from static memorization to dynamic reasoning within context.
CL-bench precisely tests this breaking point:
- how the model uses context, not just weights
- whether it can update its understanding
- whether it's capable of reasoning in complex scenarios, not just on pure QA tasks
In essence, this is a step towards models that are closer to agents than to "smart autocomplete".
Plus a strategic signal
At the same time, Tencent is launching Tencent HY Research - a blog where frontier research will be published.
This looks like a declaration:
"We're not just training large models. We want to influence how they're evaluated at all."
And this is already a level of influence on the direction of the entire field.
CL-bench isn't about +0.5% on the leaderboard.
It's about a paradigm shift:
The LLMs of the future = less rote learning, more thinking in real-world contexts.
And if this line succeeds, it's precisely such benchmarks that will determine who has truly created a "smart" model, and who has just inflated the parameters.
Project | Blog
••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore