
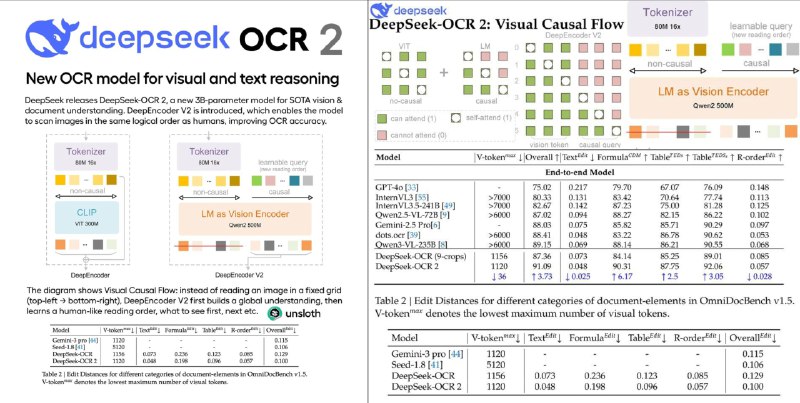
A 3B model for advanced understanding of images, documents and OCR, which reaches the SOTA level.
🟢 Why this matters?
The key novelty is DeepEncoder V2.
Unlike classic vision LLMs, which "read" the image as a grid (left-to-right, top-to-bottom), DeepEncoder V2 works closer to how a human reads:
- First, a global understanding of the image is formed
- Then, the model determines the logical order of reading - what is important first, what next
What this brings in practice
📄 Works better with complex document layouts
📊 Correctly reads tables
🧾 Links signatures and values
📰 Understands columns and structured text
🔀 More reliably processes a mixture of text and visual structure
In terms of quality
- Outperforms Gemini 3 Pro on a number of benchmarks
- Gives >4% improvement compared to the previous version of DeepSeek-OCR
And this is with a model size of just 3B parameters.
Can be launched and fine-tuned
Now, DeepSeek-OCR 2 can be conveniently launched and fine-tuned via Unsloth according to the ready-made guide.
Guide, Model, Github, Paper | #DeepSeek #ocr #opensource
••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data & ML | @DataXplore