
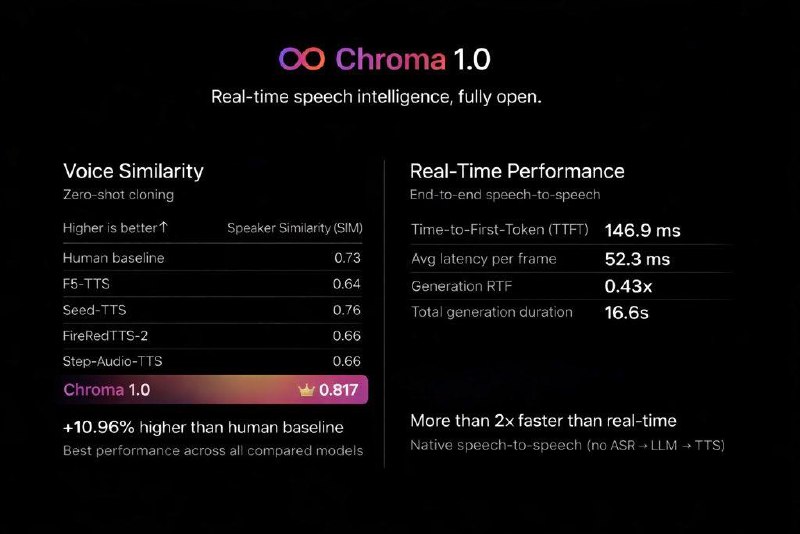
The FlashLabs team has released Chroma 1.0 - the first open-source model that can translate dialogue "voice → voice" in real time, with voice cloning.
The main thing:
this is not "recognition + text + dubbing".
This is an end-to-end system where the conversation takes place directly by voice.
What is promised in terms of characteristics:
- ⚡️ <150 ms end-to-end delay (almost like a live call)
- 🧬 high-quality voice cloning over several seconds of audio
- 📈 voice similarity SIM = 0.817 (practically identical)
- 🧠 reasoning on just 4B parameters
- 🔓 fully open weights + code
And a nice bonus: the model has already been optimized for SGLang (LMSYS) to work faster and cheaper in inference.
If this is really the case, then Chroma could become a real open-source alternative to closed voice systems.
Paper Model Code
••••••••••••••••••••••••••••••••••••••••••••••••••••
🤖 Data Science, ML & Big Data with @DataXplore