
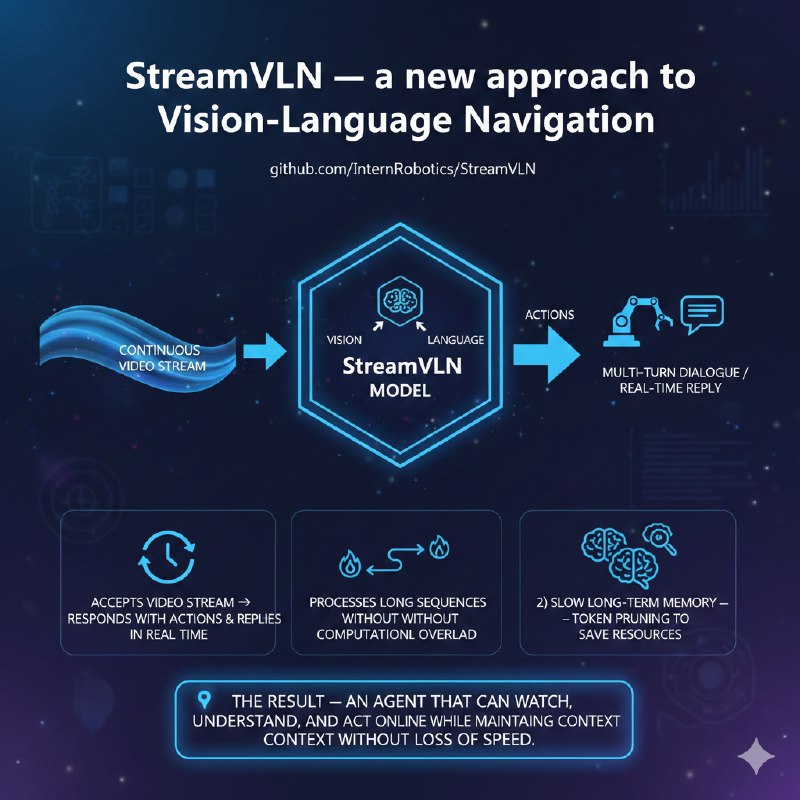
The StreamVLN model generates actions based on a continuous video stream in online mode, conducting a multi-turn dialogue.
🟢 What makes StreamVLN interesting?
☞ Based on LLaVA-Video but extended for joint modeling of vision, language, and actions.
☞ Accepts a video stream → responds with actions and replies in real time
☞ Processes long sequences without computational overload
Has two levels of memory:
1) fast dialogue memory — sliding-window KV cache
2) slow long-term memory — token pruning to save resources.
Agent that can watch, understand, and act online while maintaining context without loss of speed.
Repository
•••••••••••••••••••••••••••••••••••••
🤖 Data Science, ML & Big Data with @DataXplore