
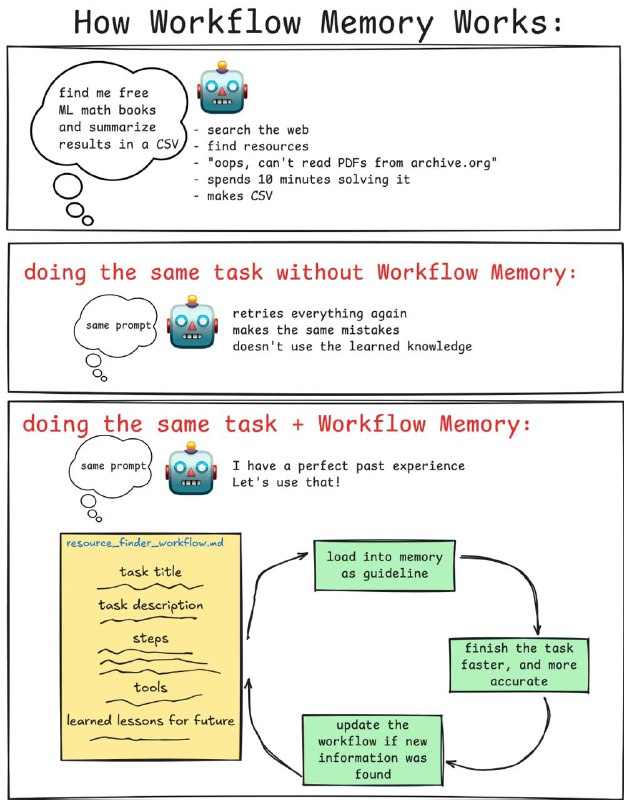
There is a simple technique no one uses that radically improves the quality (51.1%) of the agent.
🟢 Its workflow memory
Imagine the task: you ask the agent to train an ML model on your CSV. It writes PyTorch code, tries hyperparameters, edits the config, optimizes the pipeline, and delivers the final script. Everything is great. But a few days later you give a similar task, and the agent goes through the whole process again, repeats mistakes, and wastes tokens.
Workflow memory changes the rules. The agent must remember the process and its experience: what it did, what difficulties it encountered, which solutions worked, what to avoid. This is not retrying, but skill development.
At the end of the task, the agent writes key information into a regular markdown file: task description, problems, conclusions. And when starting a new task, it receives brief descriptions of past workflow.md files and chooses what will be useful.
This is a cheap way to give the agent working memory without relying on a huge context.
Result
- fewer tokens and costs
- no repeated mistakes
- real learning from experience, not starting from zero every time
You can implement this today in your agent. You only need markdown files and a well-thought-out prompt.
Github
🤖 Data Science, ML & Big Data with @DataXplore