TGViewer
Channel Public Channel
Data science/ML/AI

Data science/ML/AI

@datascience_bds

Data science and machine learning hub

Python, SQL, stats, ML, deep learning, projects, PDFs, roadmaps and AI resources.

For beginners, data scientists and ML engineers
πŸ‘‰ https://rebrand.ly/bigdatachannels

DMCA: @disclosure_bds
Contact: @mldatascientist
Subscribers
14.1K
Photos
612
Videos
7
Links
341

Showing posts older than #854 Β· Back to latest

Older Posts 20 shown
Post #853 2.63K
ChatGPT Training Explained
  • ❀ 11
Post #851 2.95K
How To Design a Neural Network
  • ❀ 10
Post #849 2.93K
Adaptive Query Execution (AQE) in Apache Spark is a feature introduced to improve query performance dynamically at runtime, based on actual data statistics collected during execution.

This makes Spark smarter and more efficient, especially when dealing with real-world messy data where planning ahead (at compile time) might be misleading.

πŸ” Importance of AQE in Spark
Runtime Optimization:

AQE adapts the execution plan on the fly using real-time stats, fixing issues that static planning can't predict.

Better Join Strategy:
If Spark detects at runtime that one table is smaller than expected, it can switch to a broadcast join instead of a slower shuffle join.

Improved Resource Usage:
By optimizing stage sizes and join plans, AQE avoids unnecessary shuffling and memory usage, leading to faster execution and lower cost.


πŸͺ“ Handling Data Skew with AQE
Data skew occurs when some partitions (e.g., specific keys) have much more data than others, slowing down those tasks.

AQE handles this using:

Skew Join Optimization:
AQE detects skewed partitions and breaks them into smaller sub-partitions, allowing Spark to process them in parallel instead of waiting on one giant slow task.

Automatic Repartitioning:
It can dynamically adjust partition sizes for better load balancing, reducing the "straggler" effect from skew.


πŸ’‘ Example:
If a join key like customer_id = 12345 appears millions of times more than others, Spark can split just that key’s data into chunks, while keeping others untouched. This makes the whole join process more balanced and efficient.

In summary, AQE improves performance, handles skew gracefully, and makes Spark queries more resilient and adaptiveβ€”especially useful in big, uneven datasets.
  • ❀ 2
  • πŸ‘ 2
Post #848 2.47K
Curve-Fitting Methods and What they Mean
  • ❀ 7
  • πŸ‘ 4
Post #846 2.83K
Linear Regression
  • ❀ 8
  • πŸ‘ 1
Post #845 2.51K
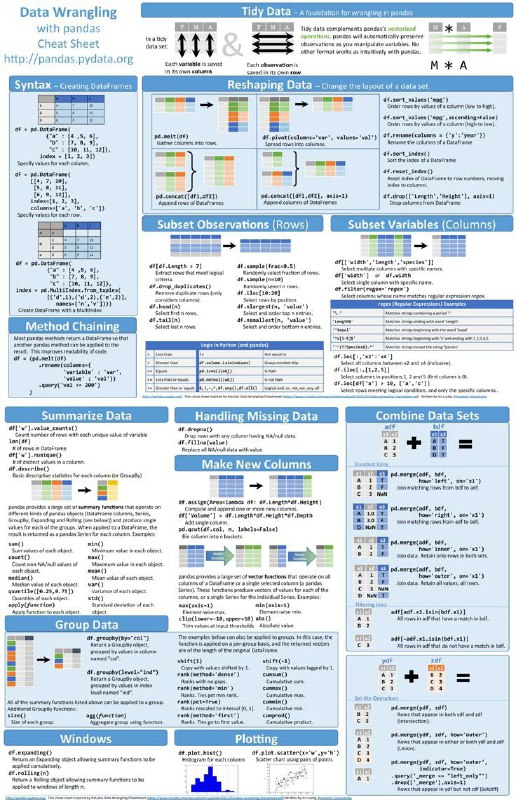
How to Merge Pandas DataFrames?
  • ❀ 8
  • πŸ‘ 2
Post #844 2.7K
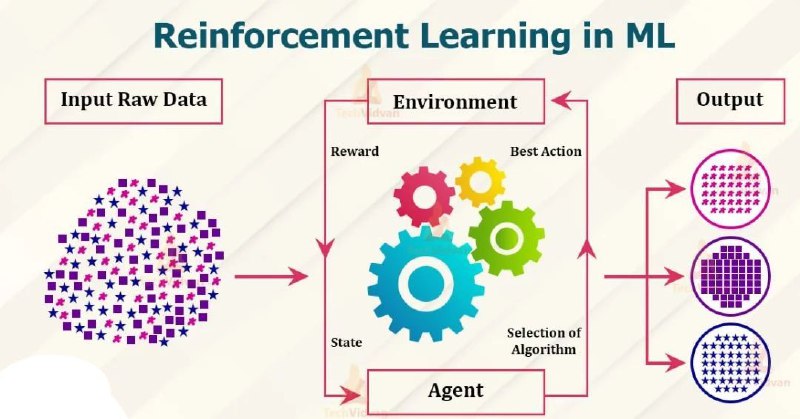
This diagram explains how Reinforcement Learning (RL) works in Machine Learning.

It starts with raw input data.

An agent interacts with an environment by selecting actions.

The environment gives feedback in the form of rewards and new states.

The agent learns which actions give the best rewards and improves over time.

The result is an optimized output, based on trial, error, and learning from feedback.
  • ❀ 11
  • πŸ‘ 1
Post #843 2.61K
Data Wrangling with Pandas Cheatsheet
  • ❀ 11
Post #842 2.68K
Kafka Usecases
  • ❀ 6
Post #841 2.76K
Roadmap for AI Engineers
  • ❀ 8
Post #840 2.88K
Popular Models for Machine Learning
  • ❀ 8
Post #839 2.68K
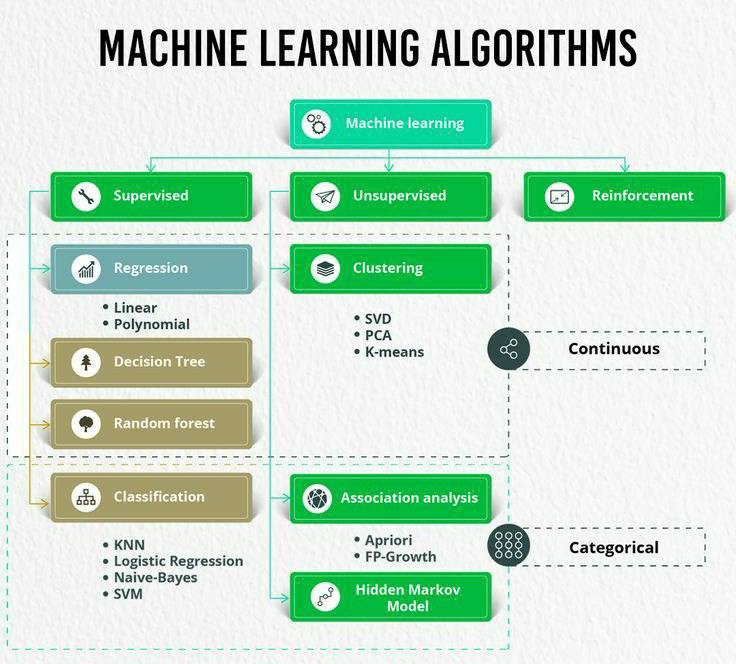
Machine Learning Algorithms
  • ❀ 7
Post #838 2.89K
Skills Needed To Become a Data Scientist
  • ❀ 6
Post #837 2.81K
Top 5 Data Science Data Terms
  • ❀ 7
Post #836 3.01K
  • ❀ 1
Post #835 3.01K
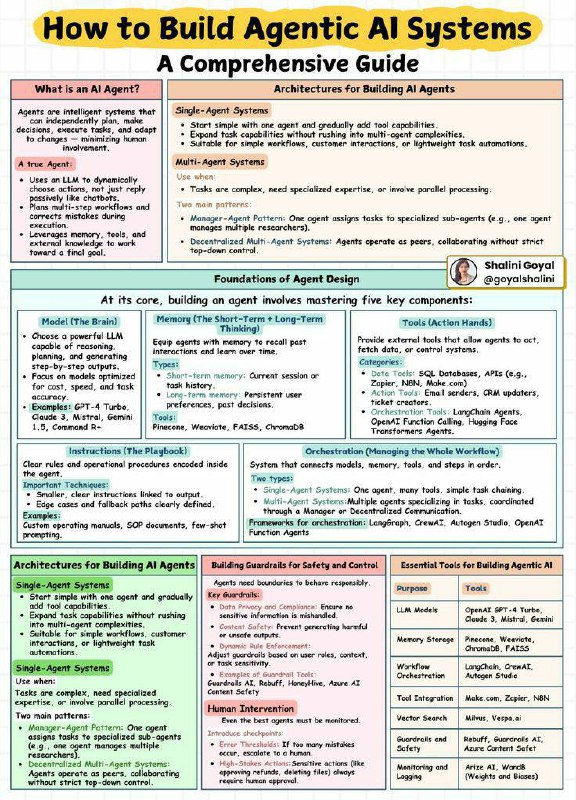
How to Build Agentic AI Systems: A Comprehensive Guide
  • ❀ 8
Post #834 2.71K
Data Science Techniques
  • ❀ 7
Older posts β†’
Threads Profile ViewerView any public Threads profile without an account.Open ThreadLook β†’Writing with AI? Make it sound human.Metric37 rewrites AI drafts so they read naturally. Free AI detector, 1,500 words free.Try Metric37 β†’