Do you want to understand the methods used to train LLMs?
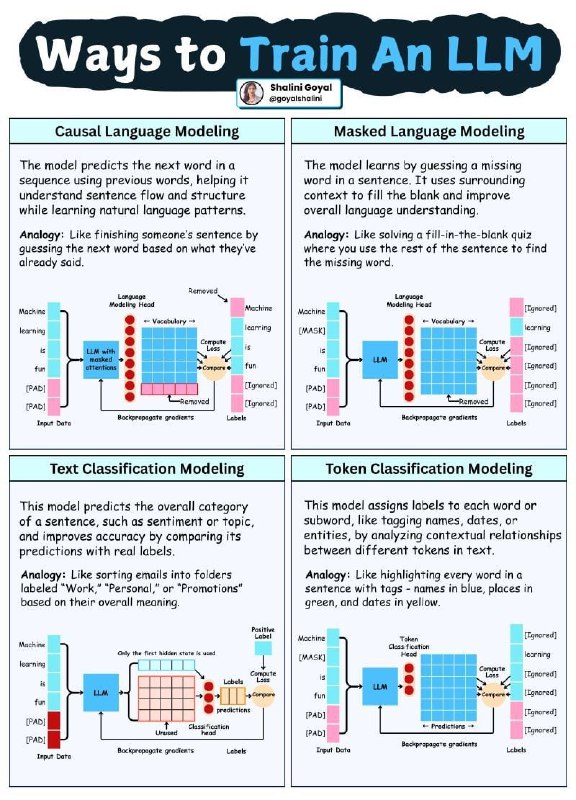
The training of large language models (LLMs) is based on various approaches that help models understand and generate text.
Each method shapes the learning process in its own way - from predicting the next word to classifying entire sentences or labeling entities.
Here are 4 common methods of training LLMs in simple language 👇
1. Causal Language Modeling
Predicts the next word in a sequence based on the previous ones. Helps the model master the natural flow of speech and the structure of sentences.
Analogy: how to finish a sentence for another person by guessing the next word.
2. Masked Language Modeling
Learns by guessing the missing words in a sentence based on the surrounding context. Improves the overall understanding of language.
Analogy: how to solve tasks with missing words.
3. Text Classification Modeling
Determines the general class of a sentence (for example, tone or topic) by comparing predictions with actual labels.
Analogy: how to sort letters into folders "Work", "Personal", or "Promotions".
4. Token Classification Modeling
Assigns labels to each word or subword - for example, highlights names, places, or dates in the text.
Analogy: how to highlight words with different colors - names in blue, places in green, dates in yellow.
These methods form the basis of modern LLMs, and each of them plays a role in making AI smarter and more useful.
https://t.me/CodeProgrammer
Post #4873
3.91K
- ❤ 8
- 👍 3