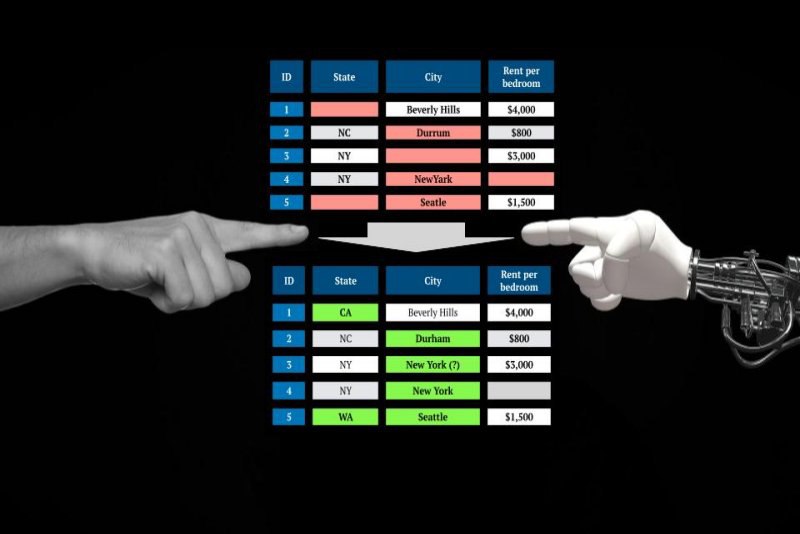
🙌🏻Data cleansing is too hard and too long? Try PClean, a new AI-system form MIT researchers written in a domain-specific probabilistic programming language for automatic data cleansing. It removes typos, duplicates, missing values, spelling errors and inconsistencies, making it easier to prepare a dataset for analysis and ML-modeling. Notably, PClean does not just mechanically cleanse data, but takes into account its semantics using generalized common sense models for judgments that can be customized for specific underlying data and error types.
The idea of probabilistic data cleansing based on declarative generalized knowledge of the research context is not new. It was published in a 2003 article by researches of the Berkley University of California. PClean develops this idea according to the trend of "explainable AI" with the realistic models of human knowledge to interpret data. Corrections in PClean based on Bayesian reasoning, whereby each alternative explanation for ambiguous data is assigned some weight to the existing probability data based on prior knowledge. An additional advantage of PClean is the ability to clean really large amounts of data, and relatively quickly. For example, in a recent 2021 study on table with 2.2 million rows of medical data, PClean found over 8,000 errors in just 7.5 hours. Finally, thanks to the principle of Bayesian probability, PClean give calibrated estimates of its uncertainty, which can be manually corrected and train the AI system.
https://news.mit.edu/2021/system-cleans-messy-data-tables-automatically-0511
Post #251
1.05K