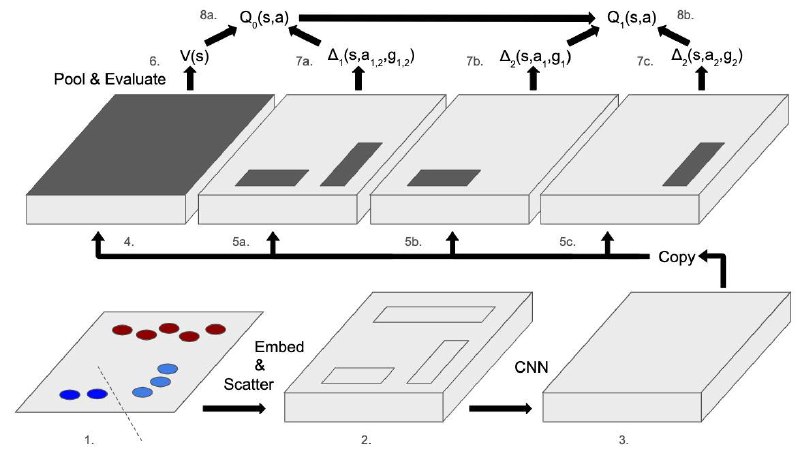
Deep Set Prediction Networks by Yan Zhang et. al. https://arxiv.org/abs/1906.06565 This paper has received a lot of attention (deservedly) in the short time it has been published.
Encoding sets in neural networks is done using permutation-equivariant (applying a function on every item) and permutation-invariant (sum, average, max) operations. (I think sum works the best, because sum is a gradient distributor and help optimization).
"Deep Sets" paper showed that theoretically this can learn any function on sets (even maximum, and the second maximum, I know it is unintuitive, but it can. theoretically!) But there are some limitations which you can read about it here (
https://www.inference.vc/deepsets-modeling-permutation-invariance/).
Similar ideas were also used and shown very effective in relation networks (
https://arxiv.org/abs/1706.01427 ) and GQNs from Eslami et. al. But this paper tries to tackle "decoding" or generating sets.
To the best of my knowledge this is one of the very few papers that actually generates "real" sets. The trick is to use a set "encoder" for decoding! Assume you have a target latent vector z for your set that you want to "decode".
Start with an initial set estimate. Encode the set estimate into the latent space. Measure error to the target z. Backpropagate error to the set estimate. Use gradient descent to update your set estimate. Repeat 10 times to arrive at a set that encodes close to your target z.
This means that each "decoding" step is a mini-optimization loop. During training you have your main optimization loop as well. The initial set estimate in fixed and learnable. This paper studies 2 set generation settings. Auto-encoding setting and supervised setting.
In auto-encoding setting you use the set encoder to encode your set into your target z and use the same encoder for "decoding". The "set loss" is Soft-L1 loss, after finding the best assignment between the estimate set and the input set using the Hungarian algorithm.
In the supervised setting, the input (e.g. image) is first mapped into the latent space (e.g. using a resent) creating the target z. An encoder maps the target set into the same latent space. The encoder is used during "decoding" as well.
In the supervised setting, the loss has 2 parts: "set loss" as in auto-encoding setting, and "representation loss" which is the l2 distance between the encoder estimate of z and target z.
Some limitations of this approach: - The Hungarian assignment of your estimated set and your target set O(n^3) has to be calculated each time. (Actually 10 times for each iteration, refer to "practical tricks" in the paper) limiting the scalability of the approach.
The set estimate is real-valued. - The set estimate is not really variable size, you have to use some masking tricks to make it seem variable size. But over all I liked the paper.
The thing I like about Yan is that he has already published his code. Also he reports mean, std over multiple runs in his experiments. This is very important IMHO and is very hard to find these days!
✴️
@AI_Python_EN